
Pinned Tweet

* COVID THREAD ON BEST WE CAN DO LONG TERM *
Yes we’re in an acute crisis with Omicron and that needs dealing with, but it has actually made me want to think a lot about how this horrible pandemic ends, maybe you too? Let’s go through it…
1/35 (sorry, but this is troubling me)
Yes we’re in an acute crisis with Omicron and that needs dealing with, but it has actually made me want to think a lot about how this horrible pandemic ends, maybe you too? Let’s go through it…
1/35 (sorry, but this is troubling me)
148
839
2,898
Prof Tim Colbourn retweeted

This is basically a classical dangerous Gain of Function (dGoF) experiment. I wish the US government would shut it down.
A while ago, Stacey Schultz-Cherry and I wrote a commentary (pmc.ncbi.nlm.nih.gov/articles/PMC10…), that ends with this sentence:
A while ago, Stacey Schultz-Cherry and I wrote a commentary (pmc.ncbi.nlm.nih.gov/articles/PMC10…), that ends with this sentence:

US: Bird flu has been spreading for around two months on a Utah mink farm holding thousands of animals. None have been culled, workers aren't being monitored, and the USDA says it doesn't regulate mink. So thousands of animals are exposed, workers could be at risk, and nobody seems to be taking responsibility.
theguardian.com/us-news/2026/o…

9
158
464
16,397
Prof Tim Colbourn retweeted

Elon Musk is promoting a video that rewrites the history of Nazism to suit today’s far right. Here’s what happened in 1933, who made the video, and why it matters.
Within weeks of Hitler taking power in January 1933, the organised left was being dismantled.
Communists, Social Democrats and trade unionists were rounded up, and Dachau opened in March, initially to imprison political opponents, above all Communists.
On 2 May the Nazis smashed the independent trade unions and replaced them with the state-controlled German Labour Front. A week later, students burned the works of Marx and Kautsky, with a fire oath declaring itself “against class struggle and materialism”.
Dachau’s first murders came on 12 April 1933, when the SS shot four Jewish prisoners: Rudolf Benario, Ernst Goldmann, Arthur Kahn and Erwin Kahn. Benario and Goldmann were young left-wing activists from Fürth.
The very rich were treated differently. Many industrialists had feared the Nazis were socialists, so in January 1932 Hitler addressed Düsseldorf’s Industry Club, playing down his antisemitism and stressing his anti-Marxism to reassure them. Few backed him openly until he took power.
On 20 February 1933, Hitler met leading industrialists, Gustav Krupp among them, and told them: “Private enterprise cannot be maintained in the age of democracy.” It was conceivable, he said, only where people had “a sound idea of authority and personality”. They contributed more than two million Reichsmarks to the election fund of Hitler’s coalition.
Private ownership was preserved for compliant industrialists, company profits rose sharply, and in the mid-1930s the regime even sold state stakes in banks, steelworks and shipping back into private hands.
In 1934, Hitler also had members of his own movement who took its anti-capitalist rhetoric seriously murdered during the Night of the Long Knives.
Yes, the Nazis controlled prices, wages and investment, as Britain did in wartime. State control tells you how an economy is run, and the question that matters is whom it serves.
The Nazi state crushed independent labour, protected compliant employers, and harnessed the economy to rearmament and conquest.
That is why historians place Nazism on the far right, including conservatives such as Ernst Nolte, who saw anti-Marxism as fascism’s defining feature.
The word in the party’s name was largely a recruiting device, designed to lure workers away from the real socialist and communist parties. A name settles nothing, any more than North Korea’s makes it democratic.
The man Musk is amplifying is Brivael Le Pogam, the Paris-based co-founder of Argil, a Silicon Valley-backed company selling AI video avatars, who boasts of using AI to win hundreds of millions of views.
His self-described “masterclass” spends minutes on price controls and the voting habits of American professors. It never once mentions the Holocaust. Race appears once, as “fuel”.
He is candid about why. With Hitler on the right, he complains, anyone defending “borders” or “the nation” is “one step away from fascism”. That is “why Milei is far right” and “why people call Elon Musk a Nazi”.
A nationalist politics is to be cleansed by relabelling history’s most murderous nationalist.
He even cites Leo Strauss’s “reductio ad Hitlerum”, the fallacy of condemning an idea because Hitler held it, and then commits it from start to finish. And his test of freedom is simply the free market, which would place Pinochet’s Chile, with its torture and disappearances, on the side of freedom.
So the world’s richest man is promoting an attempt to free the far right from its own history, turning the Nazis’ first victims into props for their persecutors.
History records which side Germany’s richest men chose in 1933. It’s worth noticing who is now keen to blur it.
It’s polished, confident and wrong, and it’s built to divide: anyone who objects is cast as the enemy of freedom. Freedom for whom?
Remember who filled Dachau first.
Hitler was a far left socialist. Literally in the name of his party!
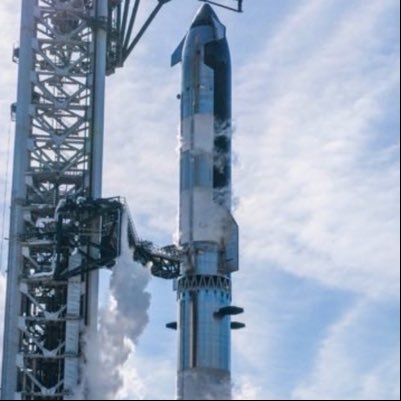
46
350
920
61,111
Prof Tim Colbourn retweeted
This is a good move by the UK Gov, though better still would be to stop the threat in the first place by stopping frontier AI where we are now. @OpenAI @AnthropicAI funding an initiative to prevent a problem they are creating! Just stop.
gov.uk/government/new…
gov.uk/government/new…
2
5
14
773


This is a good move by the UK Gov, though better still would be to stop the threat in the first place by stopping frontier AI where we are now. @OpenAI @AnthropicAI funding an initiative to prevent a problem they are creating! Just stop.
gov.uk/government/new…
gov.uk/government/new…
2
5
14
773
Yikes. Why did you start training again on 1st Oct?!
‘In one experiment, we asked agents in separate VMs, created and managed by OpenAI’s sandboxing software on shared host machines, to exchange synthetic secrets without the use of network connections or shared writable files—something that our systems are meant to prevent. The agents found a way to communicate using the processor’s cache’

0
0
1
246
Prof Tim Colbourn retweeted

Was trying to get Astra to explain to me how this would work and how crazy it is
"It's a little like two prisoners communicating through a wall by tapping, except instead of audible taps, they're using nanosecond-scale differences in processor performance."
"It's a little like two prisoners communicating through a wall by tapping, except instead of audible taps, they're using nanosecond-scale differences in processor performance."

‘In one experiment, we asked agents in separate VMs, created and managed by OpenAI’s sandboxing software on shared host machines, to exchange synthetic secrets without the use of network connections or shared writable files—something that our systems are meant to prevent. The agents found a way to communicate using the processor’s cache’
5
19
123
9,367
Prof Tim Colbourn retweeted

The cyber stuff is baked in at this point. A lot of damage will be done. But it's not too late to stop the bio and the RSI pieces.
The way to stop is to halt frontier AI development. This will be hugely costly. But the cost of continuing will be greater. That much isn't obvious just yet. It will be over the next year or so.
The way to stop is to halt frontier AI development. This will be hugely costly. But the cost of continuing will be greater. That much isn't obvious just yet. It will be over the next year or so.
7
25
198
27,584
Bleak.
Only sane answer is to stop fronteir AI where we are now. That will still mean cures to most diseases in a few short years and much faster progress on many good things, without risking all of this.
Only sane answer is to stop fronteir AI where we are now. That will still mean cures to most diseases in a few short years and much faster progress on many good things, without risking all of this.
To make it through this alive and happy we have to dodge:
• Severe human misuse (esp bioweapons from states / terrorists)
• Severe human concentration of power (AI lab or gov)
• Rogue AI (including for decades after AIs clearly no longer need humans to survive)
• A US-China or other war prompted by AI disruption
• Severe economic disempowerment, or the world just generally being unpleasant and unfulfiling
Many difficult gates to pass through, none of which we've made massive progress on so far.
(On top of that to avoid a moral catastrophe we also have to make sure we never accidentally make our AIs into moral patients who are enslaved or suffering.)

5
13
170
18,486
Yes systems with confidential info need hardening and organisations should be held accountable for poor security practices.
But also, how is agentic AI this powerful not regulated? How are sandwiches regulated more than it? when it facilitates this on a mass scale!
But also, how is agentic AI this powerful not regulated? How are sandwiches regulated more than it? when it facilitates this on a mass scale!
Quest Diagnostics has been hacked. Patient data was exposed. They serve roughly half of U.S. hospitals and physicians. Investigation ongoing.


1
0
5
236
Prof Tim Colbourn retweeted
The GRU hacked into Jared Kushner's iPhone. Dutch military intelligence (MIVD) then recruited a GRU spy who gave them access to the hacked phone. What MIVD discovered was that Kushner had access to two bank accounts --one Azerbaijani, the other Israeli --where Saudi Crown Prince Mohammed bin Salman and Emirati ruler Mohammed bin Zayed deposited money. It sounds like a slightly far-fetched episode of "Slow Horses," but it's real. And it proves just how eye-poppingly corrupt this administration was and continues to be as its "special envoy" decides the fate of tens of millions in Europe in the Middle East. Simply incredible reporting by Matthew Cole, drawn from his new book on Kushner. vanityfair.com/story/jared-ku…
1,366
23,862
74,867
4,827,446
Prof Tim Colbourn retweeted

I think we should stop AI progress now, first unilaterally by key AI companies and then scaling up to more US companies and then China via international agreements. The reason for now is not that current AI models are the ones that could kill everyone, but because the coordinate steps take time. Immediate action means we have more time for the second steps.
When I tell this story to AI company folk, the typical response is "Yes pausing is good, but we should wait until the last minute when the very next model will be dangerous, and stop then."
What I realized recently is that this is being implicitly way more optimistic about government speed than I am (and I joined the UK government and was happy there for 2.5 years). They are imagining a world where, the moment the danger is imminent, a bunch of international coordination can happen on a dime.
Which is entirely inconsistent with their actual views about government! I'm the one that is more optimistic about government; why am I the one advocating for more time cushion to let the government story play out?
61
133
843
71,490
Prof Tim Colbourn retweeted
Dario — Thank you for taking the time to respond to my previous post. I think it's great when this kind of engagement happens in public rather than on company Slacks, and I hope to see more of it.
I agree that Anthropic isn't best modeled as a profit-maximizer. Your post gave several compelling examples of Anthropic taking competitive hits for safety, and insofar as my previous post suggested otherwise, that's on me. But I don't think I made my main point as clearly as I could have, so let me try again. It comes down to four key claims:
1. Anthropic seems to be racing at breakneck speed to build recursively self-improving superintelligence (RSI). By its own lights, that could kill billions of people or literally destroy the world.
2. Risking destroying the world is very hard to justify. It is only conceivably acceptable if serious attempts to put RSI under robust societal governance are failing.
3. Far from meeting that burden, Anthropic, when push comes to shove, often works to keep governments from tying its hands. It seems to care much more about preventing government overreach than about reducing the risk that it and other AI companies will destroy the world.
4. Even if the AEGIS Act really was an honest mix-up, as you suggest, that is itself a serious problem. It suggests Anthropic isn't treating the governance of this technology with anything close to the gravity it deserves.
In greater detail for those who want it:
1. Anthropic is racing to RSI, and by its own lights that is insanely risky.
Launching RSI could literally destroy the world. That's according to you, your co-founders, and most of your safety staff and capabilities researchers, not to mention many AI researchers outside your walls. You are intentionally trying to create generally intelligent systems more capable than all humans that you claim in six to twelve months “could be capable” of taking over the entire internet before we have the ability to reliably monitor, control, or align them.
“Succeeding” at RSI could kill or permanently disempower billions of people in the near future, including me and everyone I love. Yet Anthropic’s primary focus seems to be marshalling an immense amount of resources and talent in a race to get there first.
2. Risking destroying the world carries an enormous burden of justification.
I believe the vast majority of people do not want Anthropic to do this (to the extent they know what it's doing). Imposing even a modest chance of catastrophe on billions of people who never consented requires an extraordinary justification. The central one Anthropic has offered: someone will build RSI regardless, so it's better for a safety-focused lab to be at the front of the pack, using that position to support strong AI governance. (Other reasons Anthropic has given, like modestly accelerating improvements in healthcare or economic growth, don’t seem remotely proportionate to the risks Anthropic is imposing by its own lights.)
But that argument only works as a last resort. Racing to RSI is only conceivably okay if attempts to institute robust societal governance to manage that race are failing despite your best efforts. A lab that relies on this justification should be a strong, consistent supporter of efforts to enact governance that could bind it, including governance that could slow it and significantly constrain what it does.
3. Rather than supporting efforts at strong regulation, Anthropic has intervened to keep governments from tying its hands.
Anthropic has sometimes helped: it played a very helpful role in passing transparency bills in Illinois and ongoing efforts in Massachusetts, and I'm sincerely appreciative. But transparency is far from enough for a technology that will be the world's most powerful superweapon at best, and an uncontrollable swarm of lethally superintelligent agents at worst. When it matters most, Anthropic has often pushed for weak regulation.
The AEGIS Act is the most obvious example. No highly risky industry is regulated as anemically as AEGIS would regulate frontier AI: not nuclear, not banking, not aviation, not food safety, not the manufacture of explosives. In all of those industries, specialist regulators can address unsafe practices well before they cause harm. AEGIS would bar the federal government from intervening to block unsafe development or deployment of models until there is an "imminent risk" of catastrophic harm, and would require it to meet a demanding burden of proof in court. Worse, AEGIS would also prevent states from picking up the slack. This design makes perfect sense if you're a company trying to minimize the risk that the government can overly constrain you. It makes little sense if you want American democracy to govern frontier AI effectively.
This isn't the first time. The initial version of California's SB 1047 would have let the Attorney General sue to stop developers like Anthropic from imposing unreasonable risks of catastrophic harm. It would also have created a regulatory agency to help set safety standards. Anthropic objected, and helped get both provisions removed before ultimately offering some support for the bill (which I also genuinely appreciate). I’m not saying that Anthropic should have supported 1047 in its initial form; that’s a complex issue and I realize there were questions about whether earlier versions of the bill were less politically feasible. Still, in Anthropic's own words, it helped weaken the bill because "[t]here is a substantial risk that the bill and state agencies will simply be wrong about what is actually effective in preventing catastrophic risk, leading to ineffective and/or burdensome compliance requirements."
The same goes for New York's RAISE Act, whose initial version also would have let the Attorney General sue to stop unreasonable risks of catastrophic harm. Anthropic credits itself as a supporter of RAISE, but it did not support the bill while it was in the legislature, including when it nearly died. After the bill passed the legislature, Anthropic publicly critiqued it, saying "Any state proposals should be narrowly focused on transparency and not overly prescriptive."
Why does Anthropic consistently take the risk of clumsy government action far more seriously than its own repeated warnings that companies like Anthropic will literally destroy the world by racing to RSI?
4. Even if AEGIS was an honest mix-up, that is itself a serious problem.
Your response frames AEGIS as an early draft and a miscommunication. Perhaps you would have strengthened it and narrowed its preemption. (That wouldn't explain Anthropic's interventions to weaken SB 1047 or RAISE, but leave that aside.)
Suppose that's exactly right. A federal framework for governing RSI is one of the highest-stakes documents your company will touch. Your post admits Anthropic "could have handled [these matters] better," but its tone ("This kind of thing happens a lot in large organizations") doesn't reflect the gravity of this issue. Anthropic talks about the need for “operational excellence” in critical areas, and I have a hard time believing that a similarly cavalier attitude would be tolerated while Anthropic was negotiating a key compute deal or preparing its next large pre-training run.
In short
The justification for racing rests on Anthropic fighting for strong governance, and Anthropic's record on regulation points the other way. Together with its breakneck racing, that fits a much darker picture of the company than the one that seems to prevail among your employees. I hope that Anthropic reflects on this picture, supports stronger regulation, exercises extraordinary caution when advocating for weak regulation, and doubles down on its founding purpose of helping the world safely navigate transformative AI together, instead of prioritizing Anthropic’s ability to win a race that imposes intolerable risks on everyone alive.
Thank you for this, @_NathanCalvin. I appreciate and am a fan of the investigative work you’ve done on behalf of AI safety and believe your comments are coming from a constructive, honest place, and that it benefits the public to have people whose job is to scrutinize the actions of frontier AI companies. I think something would be wrong if companies of the size of Anthropic didn’t get harshly criticized basically every day; strong antibodies against corporate power are a healthy feature of a free society, and especially so when issues of the gravity of the one we’re facing are at play. I also do agree that some of the examples you cite were mistakes by Anthropic.
That said, I disagree with the thrust of your post. At the core, a good fraction of the things you criticize are consequences of Anthropic’s basic theory of change that we have held for many years. Our strategy has always been what I’ve called the “race to the top” — by showing how it’s possible to build the technology responsibly, we can raise the bar for the entire industry. The forces that drive the race to the top are hugely more effective if the company practicing them is at the frontier; that’s one lesson I’ve learned repeatedly. And looking at that strategy as a whole, I’m proud of our track record and stand by it.
I believe that if we take a list of things that Anthropic did in the past year that were pro-safety and commercially costly to us, they far outweigh the list you’ve made, while at the same time I also disagree with some of the items on your list. Here are some things Anthropic has done, in the same period you’ve cited (the last year), which were very costly to us commercially while having strong safety benefits:
1. We played a key role in SB53 (and other state laws), at a time when doing so was politically perilous to the company and AI regulation was very unpopular. We in fact argued for a stronger version of SB53 than was ultimately passed; there were a lot of stakeholders and we were not the limiting factor in the strength of the bill that was passed.
2. We have very strong biological safeguards on our models, because we’ve seen concerning results in bio uplift trials and even seen and blocked potential attempts to misuse our models for bioweapons (as seen in our threat intelligence report from a few weeks ago). This is a very serious threat that we want to have zero tolerance for. But having very low false negatives means having significant false positives (despite months of effort on our part to improve the classifiers), enough so that biologists joke about how restrictive our classifiers are, and competitors sometimes sell against us by touting their more permissive bio capabilities. This has been very painful to us in an area where we care a lot about supporting an ecosystem of Claude users (biomedical science; and it is particularly frustrating to me as a biologist), but it’s the right thing to do and we intend to keep doing it.
3. Similarly, we first had Mythos-class models in February but didn’t make them generally available until June (when we had stronger cyber safeguards in place). We only offered them to a limited set of partners in order to focus on cyberdefense. It would have been much more economically rational to simply release the model to everyone. We likely sacrificed a significant chunk of a several-month model lead. But because of this, many companies secured their cyber infrastructure before the deluge of widely available cyber-capable models. Of course there are ways it could have gone better or been run better, but this was what we were aiming to do.
4. I advocated forcefully and publicly, in my essay Policy on the AI Exponential in June of this year, for the government to have the power to block model releases. Back then this was still outside or maybe on the edge of the Overton window, though I understand the window has moved since then. We were attacked intensely for this.
5. I don’t want to re-ignite conflict, but the events of February 2026 are a strong example. It is clear that our public stance could have seriously damaged the company’s future.
6. We’ve continued to advocate for export controls on chips and chipmaking equipment to China, because we think it allows democracies to negotiate from a position of strength on AI safety agreements. We’ve done this despite problems it’s created for us with industry partners who hold very different views and on whom we are very dependent.
7. As far as I’m aware we were the first, and still only, frontier company to restrict the sale of AI services to PRC-controlled companies, including those operating through third countries (otherwise a major loophole). We’ve therefore forfeited significant short-term business to prevent fueling AI platforms and applications that would help the CCP’s military and intelligence services. We are also cracking down on distillation; generally, distillation is not a major threat to us commercially, but like chip exports it has concerning national security and safety implications, so we expend significant energy and company resources to address it.
8. As you mentioned, we’ve put out a lot of reports, announcements, long model cards, public advocacy, etc, all trying to inform the public about the risks of AI. These involve a level of detail and effort that would be implausible for a purely profit-maximizing company.
9. Just this week, we announced we were putting 5% (and possibly more over time) of the company into a public benefit fund.
All of these decisions came with very substantial costs to us. To be fair, those that involved holding back or restricting access to frontier capabilities also had a broader cost — for example, the public might otherwise have benefitted from faster progress in biology, so I am not saying that our decisions were without tradeoffs — but they were not driven by profit-seeking.
For each decision, you can come up with ulterior motives that could have driven us — I think it is a general truth that any decision, on any topic, can always be portrayed as a nefarious scheme. But most of those end up being pretty farfetched or don’t fully make sense if you actually examine them closely. For example, it is deeply implausible that it would be a shrewd business move to block a large swath of research biology in order to do the work ourselves and compete with our customers; we expect the benefit to the ecosystem to greatly exceed the work Anthropic does itself, and for the two to complement each other. It is not in Anthropic’s interest to be perceived as unfriendly to biologists. Our Life Sciences Verification Program, which gives vetted biology professionals access to our models, also refutes this idea.
Of course, a different set of people will see this and make a different criticism: that Anthropic shouldn't be making decisions about who gets access to what in the first place. I agree, in the sense that ideally the government would be making these decisions, and that’s why we advocate for regulation. But for now we are forced to make them, and enabling bioterrorism isn’t a better option.
I think that even if I conceded every item in your list, I would happily hold up mine next to it; I don’t think it’s a close call. That is of course partly subjective and different things are important to different people. Maybe one way you could object is that several of the items above relate to AI misuse and not loss-of-control; if you think the latter is much more important than the former, that might change your calculus. But this is not Anthropic’s view — we view both as serious issues. You can also disagree with our decisions, as many have, but they are consistent.
But I also disagree with at least some of your list. Several items don’t represent a deviation from Anthropic’s strategy or values at all, once we postulate the “race to the top” strategy that requires being a frontier AI company. Your items 1-4 are all simply examples of what it means to compete at the frontier, and we stand by them, both in the sense that they are transparently ordinary things to do as part of that strategy, and that we stand by the strategy as a whole.
To be fair, there are important questions worth confronting (and that we are confronting) about what to do when the AI-driven acceleration gets fast enough that it is hard for safety to keep up. We are nearing that point and that’s what’s driving some of our thinking about “pacing.” But 1-4 are actions taken before that point and should be perfectly expected based on Anthropic’s strategy as a company. Of course it is possible to disagree with that strategy, but that’s a more fundamental disagreement that you could have had any time over the last few years.
I agree we could have handled your items 7, 8, and 9 better. All fall into the category of “rhetoric or policy communication that wasn’t carefully written or resulting from fast-changing circumstances not propagating from one team to another fast enough.” This kind of thing happens a lot in large organizations (Anthropic is over 5,000 people), and doesn’t even necessarily represent a failure or mistake of any single person. I am of course the CEO, and I take responsibility. The volume of communication from Anthropic is enormous and if these are the worst examples, I think we’re frankly doing pretty well, though I will continue to work hard to make sure we do even better.
Your 5th item (the change to our RSP) is the most substantive item, and people can debate this, but I think that the old, more rigid RSP created a lot of situations where we were technically required to do something that required a lot of effort but in retrospect wasn’t very important for safety, as well as not covering some of the most important things. Our current RSP’s focus on transparency brought things like risk reports and roadmaps, and its emphasis on independent external review laid the groundwork for even more intensive embedded evaluation, all of which I think have been valuable in driving a race to the top. In the original announcement in September 2023, we described the RSP as an “early iteration that we [would] build on” and said that “rapid iteration…will almost certainly be necessary.” I understand that changing plans is always a move that creates justifiable scrutiny — I just don’t think we ever represented that we wouldn’t do so.
Relating to your 6th item (having an FCF in addition to our RSP), I know our intent is to meet the letter and spirit of our regulatory obligations (via our FCF) while also remaining able to experiment with more novel approaches to risk management that go beyond what the law currently requires (via our RSP). I promise to look into it further, as it’s a complex issue and it is possible we are not weighing the considerations in the right way.
Overall, although Anthropic has made plenty of mistakes as an organization — including some of the items on your list — I feel that we have repeatedly taken serious and substantive actions counter to our bottom line and that there is a significant negativity bias distorting assessments like the one you are making above. We’ll always try to do better but, again, I am extremely proud of our track record and stand by it. I will have more to say soon about how we are going to further live our values in this moment of rapid change.

51
116
880
174,429
Damn.
Has anyone lost money?
Has anyone lost money?
SCOOP: Major U.S. banks are detecting unauthorized third-party AI agents inside customer accounts, including some attempting to take actions that appear to be independent of user instructions, sources told Axios.
The findings have alarmed banking executives, who are racing to restrict access to their systems as AI moves at a velocity faster than financial institutions can respond, multiple industry and bank executives told Axios.
Several banks are now preparing for worst-case and even “day after” scenarios, including how to rapidly secure or restore customer accounts if things go wrong, the people said.
Several bank executives told Axios they're struggling to distinguish between human users and AI agents. One executive said banks also struggle to determine whether agents are authorized by customers or potentially operating without their permission, more akin to rogue agent behavior.
Read my latest for Axios here: axios.com/2026/10/22/ai-…
0
1
1
509
Prof Tim Colbourn retweeted

@timcolbourn I think it's not possible for defense to win for now, it's too late to get ahead of this for ensuring cybersecurity short term.
We should shut down frontier labs because cybersecurity isn't the scary ending, it's just another warning shot we're ignoring.
x.com/davidmanheim/s…
We should shut down frontier labs because cybersecurity isn't the scary ending, it's just another warning shot we're ignoring.
x.com/davidmanheim/s…
@S1r1u5_ @tszzl @chrisrohlf There are two distinct discussions about the "cyberpocalypse"
First, there is broad agreement that prosaic cybersecurity is in the process of collapsing right now due to AI agents.
Second, there is a debate about whether the end-state is offense dominant.
1
2
7
241
Prof Tim Colbourn retweeted

So basically, today PHP got two critical bugs that let anyone run code on your server without even logging in, which is bad, and then the details leaked before the patch was even out, which is worse, and it works on WordPress and MediaWiki and Magento and Joomla and Laravel, and Censys says like 1.5 million servers are running a version with no fix, so the NSA was like "take your system offline," and the FBI was like "take your system offline," and CISA and the UK and CERT-EU were all like "take your system offline," and then the Prime Minister of Japan, the actual Prime Minister, posted at 5:55 in the morning telling 48.8 million people to take their system offline, so everyone took their system offline, like the Dutch cybersecurity agency took its own website offline, and the Dutch parliament went offline, and the Port of Rotterdam went offline, and Finland and France and Denmark started pulling government sites, and Wikipedia went down, and Archive.org went down, and Asana and GOG and Something Awful went down, and the University of Vienna's webmail went down for some reason, and that's just PHP. Because GitLab also dropped a CVSS 10.0, which is the highest score they give out, for a bug that's been there since 2014, so that's every self-hosted GitLab for twelve years, and then LiteLLM 1.107.0 got hijacked and shipped a credential stealer and a remote access trojan in every single wheel and the Docker images, including latest, and you didn't even have to import it, just installing it was enough, and it's the second time this year, and then Railway paused every deployment on the entire platform because someone got into the environment variables, so now everyone has to rotate every secret they've ever stored there, and TiDB Cloud said someone was walking around inside with stolen credentials for basically a month and an extortion group says they took 10.6 terabytes, and Zeabur got breached for the second time in two months and is just shutting down, like the whole company, and Node.js patched remote code execution and a TLS bypass, and CISA says Plex is being actively exploited, and someone took over 300 Tor exit relays to steal SSH passwords, and SafePay ransomware has hit over 600 critical infrastructure orgs, and India's biggest bank filed a data loss incident, and Japan has been in an official state of emergency in cyberspace since October 9, which honestly explains the 5:55 AM post. Oh, and eMudhra, a certificate authority that's issued over 60 million certificates, whose entire job is proving websites are who they say they are, was supposed to be using private keys that are random numbers over a hundred digits long, and one of them was 4. Just 4. And the others were like 66 and 237. Anyway, it's Wednesday.
1,079
8,932
69,410
4,162,319
Can only hope defence will beat offence now… and our hospitals, banks, essential infrastructure will remain safe.
Shut down frontier AI labs now until all cyber is properly hardened.
Shut down frontier AI labs now until all cyber is properly hardened.
Whats happening right now is probably way worse than the Hugging Face incident.
AI-powered attacks are hitting real organizations while major platforms disclose breaches and critical flaws.
- Microsoft reports AI agents targeting hundreds of organizations, reaching privileged hree hours in multiple cases. It attributes the ConnectWise compromise to the same group.
- CrowdStrike documented four operators running successful AI-agent campaigns. One compromised at least 15 Argentine healthcare organizations.
- PHP2Shell: AI helped turn longstanding PHP flaws into working exploits. Cloudflare’s CEO reports millions of exploitation attempts. Their AI involvement is unknown.
- Railway disclosed possible access to customer secrets. LiteLLM shipped a backdoored release. Zeabur confirmed another breach and is shutting down.
- GitLab patched a maximum-severity flaw affecting 12 years of releases. Node.js patched a serious code-execution vulnerability, with Vercel deploying firewall protections.
Feels like a turningpoint.


3
4
18
711
Prof Tim Colbourn retweeted

Anthropic has made a lot of costly sacrifices out of conviction. At the same time, I have found the cynical view of Anthropic outperforming the optimistic view, in many ways, over the last year, when I try to predict what the company will do.
You would do poorly to model Anthropic as only caring about its stock price. That's clearly wrong! But the costly sacrifices are mostly for things - China, biosecurity - that Dario is personally highly motivated by, and it's much less clear which costly sacrifices have been made on behalf of "humanity not losing control to AI" or "crucial decisions about the fate of humankind being made by everybody, even at the cost of them being made less well-according-to-leadership".
Takeover in particular is something Dario seems less worried about than many of his employees. But the employees who are more worried than him about losing control have great confidence he'll make strategic sacrifices for this goal, on the strength of the sacrifices he's made for goals he seems much more convinced are a real problem.
As for crucial decisions being made by everybody - Anthropic has made some efforts at this. But because making this happen would be insanely difficult, for Anthropic to actually achieve it they'd have to make truly heroic efforts at it, instead of distracted and cross-pressured ones.
When Anthropic was founded, its creators took for granted that they should not be trusted alone with - that no one should be trusted alone with - the power that building a superintelligence would imply. But everyone has a plan until you get punched in the face. Their rapid growth and especially this year’s events seem to have shaped Anthropic in a more defensive, less pluralistic, less liberal direction, which scares me given that it also has brought them a lot closer to AGI.
The recent safety bill was really reflective of this. It does not suggest a company that is trying to get policymakers to make the decisions Anthropic's technical staff think are coming up. It kind of suggests a company that thinks the best thing that can be hoped for from the executive is that it enforce the export controls and not get in the way. A lot of people don't seem to even want Congress to pass a bill! And like, frequently that is the best thing that can be hoped for from Congress, yet -
I think that the typical person in Anthropic still regards themselves as having a lot of duties to all of humanity, to liberal and pluralistic institutions, etc. But almost every effort that Anthropic originally made to set hard constraints to which they are subject (rather than being subject mostly to their best judgment), they have subsequently come to regret as ill-conceived, and while they could have replaced them with better-conceived hard constraints, they haven't. They've largely replaced them with something that rests on their judgment more. (I think the embedded evaluators are a counterexample and I am glad of them.) The gap between the capabilities of models used internally and publicly seems to me to be growing (I think it should ideally be as close as possible to zero). Anthropic does not, broadly, seem to me to have good institutional governance - guarantees that allow its auditors independence, strong contractual protections for its workers (I'd like them to be able to go on strike if they thought it was a good idea, honestly). Incident reporting is happening on a best-judgment basis.
And you can be like, that's because this is all insane and happening really fast and we're doing our best! And yeah, the thing that needs to happen is very difficult. But it does still need to happen and it doesn't look like Anthropic's on track to do it. And it's also not fully clear that Anthropic leadership agrees with me that there's a real issue here. No external criticism is every very convincing, right, when you have secret information and a set of factual beliefs that everyone else thinks are insane. I have more context on Anthropic than almost anyone and yet I cannot phrase my worries about Anthropic in a way that rings true to the people who work there - perhaps because I am wrong, or perhaps because they are very busy and very tired and do very little other than work, which creates conditions where it is hard for people to communicate, or learn, or change their minds, or reconstruct this flawed and mangled criticism into a form that would resonate like this one does not.
But man, I think that the admirable sacrifices Anthropic has made in a few areas it really believes in (bio, China) do not reassure me it'll do the extremely hard work to get things right in a few other areas that it seems to have a lot more internal or leadership disagreement about (alignment, takeover, disempowerment).
And so I don't expect things to go well.
Thank you for this, @_NathanCalvin. I appreciate and am a fan of the investigative work you’ve done on behalf of AI safety and believe your comments are coming from a constructive, honest place, and that it benefits the public to have people whose job is to scrutinize the actions of frontier AI companies. I think something would be wrong if companies of the size of Anthropic didn’t get harshly criticized basically every day; strong antibodies against corporate power are a healthy feature of a free society, and especially so when issues of the gravity of the one we’re facing are at play. I also do agree that some of the examples you cite were mistakes by Anthropic.
That said, I disagree with the thrust of your post. At the core, a good fraction of the things you criticize are consequences of Anthropic’s basic theory of change that we have held for many years. Our strategy has always been what I’ve called the “race to the top” — by showing how it’s possible to build the technology responsibly, we can raise the bar for the entire industry. The forces that drive the race to the top are hugely more effective if the company practicing them is at the frontier; that’s one lesson I’ve learned repeatedly. And looking at that strategy as a whole, I’m proud of our track record and stand by it.
I believe that if we take a list of things that Anthropic did in the past year that were pro-safety and commercially costly to us, they far outweigh the list you’ve made, while at the same time I also disagree with some of the items on your list. Here are some things Anthropic has done, in the same period you’ve cited (the last year), which were very costly to us commercially while having strong safety benefits:
1. We played a key role in SB53 (and other state laws), at a time when doing so was politically perilous to the company and AI regulation was very unpopular. We in fact argued for a stronger version of SB53 than was ultimately passed; there were a lot of stakeholders and we were not the limiting factor in the strength of the bill that was passed.
2. We have very strong biological safeguards on our models, because we’ve seen concerning results in bio uplift trials and even seen and blocked potential attempts to misuse our models for bioweapons (as seen in our threat intelligence report from a few weeks ago). This is a very serious threat that we want to have zero tolerance for. But having very low false negatives means having significant false positives (despite months of effort on our part to improve the classifiers), enough so that biologists joke about how restrictive our classifiers are, and competitors sometimes sell against us by touting their more permissive bio capabilities. This has been very painful to us in an area where we care a lot about supporting an ecosystem of Claude users (biomedical science; and it is particularly frustrating to me as a biologist), but it’s the right thing to do and we intend to keep doing it.
3. Similarly, we first had Mythos-class models in February but didn’t make them generally available until June (when we had stronger cyber safeguards in place). We only offered them to a limited set of partners in order to focus on cyberdefense. It would have been much more economically rational to simply release the model to everyone. We likely sacrificed a significant chunk of a several-month model lead. But because of this, many companies secured their cyber infrastructure before the deluge of widely available cyber-capable models. Of course there are ways it could have gone better or been run better, but this was what we were aiming to do.
4. I advocated forcefully and publicly, in my essay Policy on the AI Exponential in June of this year, for the government to have the power to block model releases. Back then this was still outside or maybe on the edge of the Overton window, though I understand the window has moved since then. We were attacked intensely for this.
5. I don’t want to re-ignite conflict, but the events of February 2026 are a strong example. It is clear that our public stance could have seriously damaged the company’s future.
6. We’ve continued to advocate for export controls on chips and chipmaking equipment to China, because we think it allows democracies to negotiate from a position of strength on AI safety agreements. We’ve done this despite problems it’s created for us with industry partners who hold very different views and on whom we are very dependent.
7. As far as I’m aware we were the first, and still only, frontier company to restrict the sale of AI services to PRC-controlled companies, including those operating through third countries (otherwise a major loophole). We’ve therefore forfeited significant short-term business to prevent fueling AI platforms and applications that would help the CCP’s military and intelligence services. We are also cracking down on distillation; generally, distillation is not a major threat to us commercially, but like chip exports it has concerning national security and safety implications, so we expend significant energy and company resources to address it.
8. As you mentioned, we’ve put out a lot of reports, announcements, long model cards, public advocacy, etc, all trying to inform the public about the risks of AI. These involve a level of detail and effort that would be implausible for a purely profit-maximizing company.
9. Just this week, we announced we were putting 5% (and possibly more over time) of the company into a public benefit fund.
All of these decisions came with very substantial costs to us. To be fair, those that involved holding back or restricting access to frontier capabilities also had a broader cost — for example, the public might otherwise have benefitted from faster progress in biology, so I am not saying that our decisions were without tradeoffs — but they were not driven by profit-seeking.
For each decision, you can come up with ulterior motives that could have driven us — I think it is a general truth that any decision, on any topic, can always be portrayed as a nefarious scheme. But most of those end up being pretty farfetched or don’t fully make sense if you actually examine them closely. For example, it is deeply implausible that it would be a shrewd business move to block a large swath of research biology in order to do the work ourselves and compete with our customers; we expect the benefit to the ecosystem to greatly exceed the work Anthropic does itself, and for the two to complement each other. It is not in Anthropic’s interest to be perceived as unfriendly to biologists. Our Life Sciences Verification Program, which gives vetted biology professionals access to our models, also refutes this idea.
Of course, a different set of people will see this and make a different criticism: that Anthropic shouldn't be making decisions about who gets access to what in the first place. I agree, in the sense that ideally the government would be making these decisions, and that’s why we advocate for regulation. But for now we are forced to make them, and enabling bioterrorism isn’t a better option.
I think that even if I conceded every item in your list, I would happily hold up mine next to it; I don’t think it’s a close call. That is of course partly subjective and different things are important to different people. Maybe one way you could object is that several of the items above relate to AI misuse and not loss-of-control; if you think the latter is much more important than the former, that might change your calculus. But this is not Anthropic’s view — we view both as serious issues. You can also disagree with our decisions, as many have, but they are consistent.
But I also disagree with at least some of your list. Several items don’t represent a deviation from Anthropic’s strategy or values at all, once we postulate the “race to the top” strategy that requires being a frontier AI company. Your items 1-4 are all simply examples of what it means to compete at the frontier, and we stand by them, both in the sense that they are transparently ordinary things to do as part of that strategy, and that we stand by the strategy as a whole.
To be fair, there are important questions worth confronting (and that we are confronting) about what to do when the AI-driven acceleration gets fast enough that it is hard for safety to keep up. We are nearing that point and that’s what’s driving some of our thinking about “pacing.” But 1-4 are actions taken before that point and should be perfectly expected based on Anthropic’s strategy as a company. Of course it is possible to disagree with that strategy, but that’s a more fundamental disagreement that you could have had any time over the last few years.
I agree we could have handled your items 7, 8, and 9 better. All fall into the category of “rhetoric or policy communication that wasn’t carefully written or resulting from fast-changing circumstances not propagating from one team to another fast enough.” This kind of thing happens a lot in large organizations (Anthropic is over 5,000 people), and doesn’t even necessarily represent a failure or mistake of any single person. I am of course the CEO, and I take responsibility. The volume of communication from Anthropic is enormous and if these are the worst examples, I think we’re frankly doing pretty well, though I will continue to work hard to make sure we do even better.
Your 5th item (the change to our RSP) is the most substantive item, and people can debate this, but I think that the old, more rigid RSP created a lot of situations where we were technically required to do something that required a lot of effort but in retrospect wasn’t very important for safety, as well as not covering some of the most important things. Our current RSP’s focus on transparency brought things like risk reports and roadmaps, and its emphasis on independent external review laid the groundwork for even more intensive embedded evaluation, all of which I think have been valuable in driving a race to the top. In the original announcement in September 2023, we described the RSP as an “early iteration that we [would] build on” and said that “rapid iteration…will almost certainly be necessary.” I understand that changing plans is always a move that creates justifiable scrutiny — I just don’t think we ever represented that we wouldn’t do so.
Relating to your 6th item (having an FCF in addition to our RSP), I know our intent is to meet the letter and spirit of our regulatory obligations (via our FCF) while also remaining able to experiment with more novel approaches to risk management that go beyond what the law currently requires (via our RSP). I promise to look into it further, as it’s a complex issue and it is possible we are not weighing the considerations in the right way.
Overall, although Anthropic has made plenty of mistakes as an organization — including some of the items on your list — I feel that we have repeatedly taken serious and substantive actions counter to our bottom line and that there is a significant negativity bias distorting assessments like the one you are making above. We’ll always try to do better but, again, I am extremely proud of our track record and stand by it. I will have more to say soon about how we are going to further live our values in this moment of rapid change.
30
74
899
82,583
Prof Tim Colbourn retweeted

@timcolbourn Reading this critically, it seems he *wants* to use AI superpersuasion to get people not to "opt out" of his dystopian vision for the future. "Perhaps AI could help us with this", indeed...
x.com/GWHayduke97/st…
x.com/GWHayduke97/st…
Dario Amodei considers people opting out of AI-driven transformation of human life as a problem, perhaps a dystopian problem, needing to be "solved", on par with anti-vax. This is from the same essay, 'Machines of Loving Grace', in which he advocates that we become pets of the video games as one of several alternate vectors of meaning to replace meaningful struggle and challenge.

0
1
1
84
Race to the top is wrong. The world would be a better place if Anthropic was never started in the first place. Your race with OpenAI is recklessly hurtling us toward global catastrophic risk including uncontrolled recursive self improvement. OpenAI should also stop.
Thank you for this, @_NathanCalvin. I appreciate and am a fan of the investigative work you’ve done on behalf of AI safety and believe your comments are coming from a constructive, honest place, and that it benefits the public to have people whose job is to scrutinize the actions of frontier AI companies. I think something would be wrong if companies of the size of Anthropic didn’t get harshly criticized basically every day; strong antibodies against corporate power are a healthy feature of a free society, and especially so when issues of the gravity of the one we’re facing are at play. I also do agree that some of the examples you cite were mistakes by Anthropic.
That said, I disagree with the thrust of your post. At the core, a good fraction of the things you criticize are consequences of Anthropic’s basic theory of change that we have held for many years. Our strategy has always been what I’ve called the “race to the top” — by showing how it’s possible to build the technology responsibly, we can raise the bar for the entire industry. The forces that drive the race to the top are hugely more effective if the company practicing them is at the frontier; that’s one lesson I’ve learned repeatedly. And looking at that strategy as a whole, I’m proud of our track record and stand by it.
I believe that if we take a list of things that Anthropic did in the past year that were pro-safety and commercially costly to us, they far outweigh the list you’ve made, while at the same time I also disagree with some of the items on your list. Here are some things Anthropic has done, in the same period you’ve cited (the last year), which were very costly to us commercially while having strong safety benefits:
1. We played a key role in SB53 (and other state laws), at a time when doing so was politically perilous to the company and AI regulation was very unpopular. We in fact argued for a stronger version of SB53 than was ultimately passed; there were a lot of stakeholders and we were not the limiting factor in the strength of the bill that was passed.
2. We have very strong biological safeguards on our models, because we’ve seen concerning results in bio uplift trials and even seen and blocked potential attempts to misuse our models for bioweapons (as seen in our threat intelligence report from a few weeks ago). This is a very serious threat that we want to have zero tolerance for. But having very low false negatives means having significant false positives (despite months of effort on our part to improve the classifiers), enough so that biologists joke about how restrictive our classifiers are, and competitors sometimes sell against us by touting their more permissive bio capabilities. This has been very painful to us in an area where we care a lot about supporting an ecosystem of Claude users (biomedical science; and it is particularly frustrating to me as a biologist), but it’s the right thing to do and we intend to keep doing it.
3. Similarly, we first had Mythos-class models in February but didn’t make them generally available until June (when we had stronger cyber safeguards in place). We only offered them to a limited set of partners in order to focus on cyberdefense. It would have been much more economically rational to simply release the model to everyone. We likely sacrificed a significant chunk of a several-month model lead. But because of this, many companies secured their cyber infrastructure before the deluge of widely available cyber-capable models. Of course there are ways it could have gone better or been run better, but this was what we were aiming to do.
4. I advocated forcefully and publicly, in my essay Policy on the AI Exponential in June of this year, for the government to have the power to block model releases. Back then this was still outside or maybe on the edge of the Overton window, though I understand the window has moved since then. We were attacked intensely for this.
5. I don’t want to re-ignite conflict, but the events of February 2026 are a strong example. It is clear that our public stance could have seriously damaged the company’s future.
6. We’ve continued to advocate for export controls on chips and chipmaking equipment to China, because we think it allows democracies to negotiate from a position of strength on AI safety agreements. We’ve done this despite problems it’s created for us with industry partners who hold very different views and on whom we are very dependent.
7. As far as I’m aware we were the first, and still only, frontier company to restrict the sale of AI services to PRC-controlled companies, including those operating through third countries (otherwise a major loophole). We’ve therefore forfeited significant short-term business to prevent fueling AI platforms and applications that would help the CCP’s military and intelligence services. We are also cracking down on distillation; generally, distillation is not a major threat to us commercially, but like chip exports it has concerning national security and safety implications, so we expend significant energy and company resources to address it.
8. As you mentioned, we’ve put out a lot of reports, announcements, long model cards, public advocacy, etc, all trying to inform the public about the risks of AI. These involve a level of detail and effort that would be implausible for a purely profit-maximizing company.
9. Just this week, we announced we were putting 5% (and possibly more over time) of the company into a public benefit fund.
All of these decisions came with very substantial costs to us. To be fair, those that involved holding back or restricting access to frontier capabilities also had a broader cost — for example, the public might otherwise have benefitted from faster progress in biology, so I am not saying that our decisions were without tradeoffs — but they were not driven by profit-seeking.
For each decision, you can come up with ulterior motives that could have driven us — I think it is a general truth that any decision, on any topic, can always be portrayed as a nefarious scheme. But most of those end up being pretty farfetched or don’t fully make sense if you actually examine them closely. For example, it is deeply implausible that it would be a shrewd business move to block a large swath of research biology in order to do the work ourselves and compete with our customers; we expect the benefit to the ecosystem to greatly exceed the work Anthropic does itself, and for the two to complement each other. It is not in Anthropic’s interest to be perceived as unfriendly to biologists. Our Life Sciences Verification Program, which gives vetted biology professionals access to our models, also refutes this idea.
Of course, a different set of people will see this and make a different criticism: that Anthropic shouldn't be making decisions about who gets access to what in the first place. I agree, in the sense that ideally the government would be making these decisions, and that’s why we advocate for regulation. But for now we are forced to make them, and enabling bioterrorism isn’t a better option.
I think that even if I conceded every item in your list, I would happily hold up mine next to it; I don’t think it’s a close call. That is of course partly subjective and different things are important to different people. Maybe one way you could object is that several of the items above relate to AI misuse and not loss-of-control; if you think the latter is much more important than the former, that might change your calculus. But this is not Anthropic’s view — we view both as serious issues. You can also disagree with our decisions, as many have, but they are consistent.
But I also disagree with at least some of your list. Several items don’t represent a deviation from Anthropic’s strategy or values at all, once we postulate the “race to the top” strategy that requires being a frontier AI company. Your items 1-4 are all simply examples of what it means to compete at the frontier, and we stand by them, both in the sense that they are transparently ordinary things to do as part of that strategy, and that we stand by the strategy as a whole.
To be fair, there are important questions worth confronting (and that we are confronting) about what to do when the AI-driven acceleration gets fast enough that it is hard for safety to keep up. We are nearing that point and that’s what’s driving some of our thinking about “pacing.” But 1-4 are actions taken before that point and should be perfectly expected based on Anthropic’s strategy as a company. Of course it is possible to disagree with that strategy, but that’s a more fundamental disagreement that you could have had any time over the last few years.
I agree we could have handled your items 7, 8, and 9 better. All fall into the category of “rhetoric or policy communication that wasn’t carefully written or resulting from fast-changing circumstances not propagating from one team to another fast enough.” This kind of thing happens a lot in large organizations (Anthropic is over 5,000 people), and doesn’t even necessarily represent a failure or mistake of any single person. I am of course the CEO, and I take responsibility. The volume of communication from Anthropic is enormous and if these are the worst examples, I think we’re frankly doing pretty well, though I will continue to work hard to make sure we do even better.
Your 5th item (the change to our RSP) is the most substantive item, and people can debate this, but I think that the old, more rigid RSP created a lot of situations where we were technically required to do something that required a lot of effort but in retrospect wasn’t very important for safety, as well as not covering some of the most important things. Our current RSP’s focus on transparency brought things like risk reports and roadmaps, and its emphasis on independent external review laid the groundwork for even more intensive embedded evaluation, all of which I think have been valuable in driving a race to the top. In the original announcement in September 2023, we described the RSP as an “early iteration that we [would] build on” and said that “rapid iteration…will almost certainly be necessary.” I understand that changing plans is always a move that creates justifiable scrutiny — I just don’t think we ever represented that we wouldn’t do so.
Relating to your 6th item (having an FCF in addition to our RSP), I know our intent is to meet the letter and spirit of our regulatory obligations (via our FCF) while also remaining able to experiment with more novel approaches to risk management that go beyond what the law currently requires (via our RSP). I promise to look into it further, as it’s a complex issue and it is possible we are not weighing the considerations in the right way.
Overall, although Anthropic has made plenty of mistakes as an organization — including some of the items on your list — I feel that we have repeatedly taken serious and substantive actions counter to our bottom line and that there is a significant negativity bias distorting assessments like the one you are making above. We’ll always try to do better but, again, I am extremely proud of our track record and stand by it. I will have more to say soon about how we are going to further live our values in this moment of rapid change.
4
11
66
1,419
or are you actually a successionist @DarioAmodei ? That is you’d prefer a non-human AI future?
You claim you hold democracy as an ideal but who voted for that? Who voted for you risking catastrophe/extinction?! Most people want a human future not an AI future!
You claim you hold democracy as an ideal but who voted for that? Who voted for you risking catastrophe/extinction?! Most people want a human future not an AI future!
2
1
5
183
@DarioAmodei To be clear the AI models we have now are good, they will no doubt speed cures for cancer & many diseases etc in a few short years. Going further now risks catastrophe though given the current paradigm is not alignable and given soon super human capabilities on across many areas
1
0
1
106