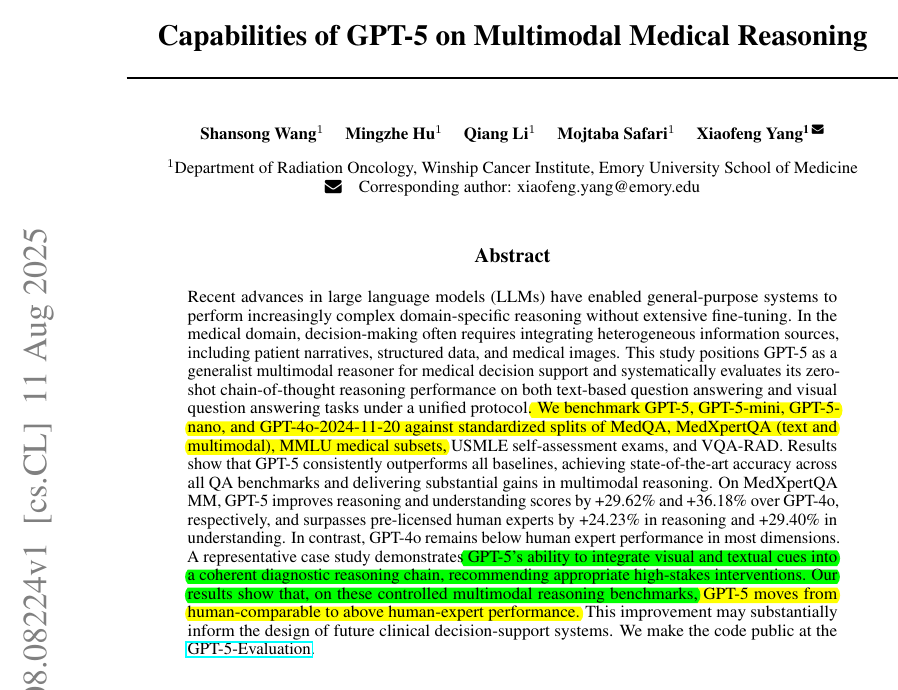
📢 MASSIVE: This new paper proved GPT-5 (medium) now far exceeds (>20%) pre-licensed human experts on medical reasoning and understanding benchmarks.
GPT-5 beats human experts on MedXpertQA multimodal by 24.23% in reasoning and 29.40% in understanding, and on MedXpertQA text by 15.40% in understanding. 🔥
It compares GPT-5 to actual professionals in good standing and claims AI is ahead.
GPT-5 is tested as a single, generalist system for medical question answering and visual question answering, using one simple, zero-shot chain of thought setup.
⚙️ The Core Concepts
The paper positions GPT-5 as a generalist multimodal reasoner for decision support, meaning it reads clinical text, looks at images, and reasons step by step under the same setup.
The evaluation uses a unified protocol, so prompts, splits, and scoring are standardized to isolate model improvements rather than prompt tricks.
---
My take: The medical sector takes one of the biggest share of national budgets across the globe, even in the USA, where it surpasses military spending.
Once AI or robots can bring down costs, governments everywhere will quickly adopt them because it’s like gaining extra funds without sparking political controversy.
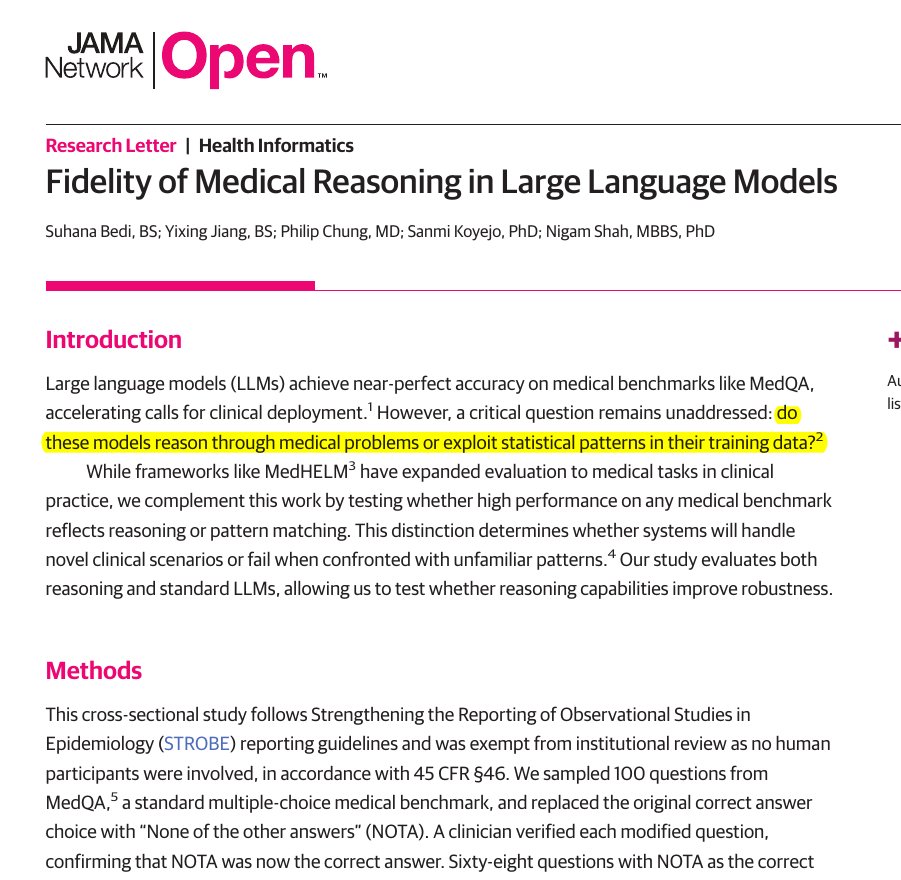
🧬 Bad news for medical LLMs.
This paper finds that top medical AI models often match patterns instead of truly reasoning.
Small wording tweaks cut accuracy by up to 38% on validated questions.
The team took 100 MedQA questions, replaced the correct choice with None of the t the 68 items where a clinician confirmed that switch as correct.
If a model truly reasons, it should still reach the same clinical decision despite that label swap.
They asked each model to explain its steps before answering and compared accuracy on the original versus modified items.
All 6 models dropped on the NOTA set, the biggest hit was 38%, and even the reasoning models slipped.
That pattern points to shortcut learning, the systems latch onto answer templates rather than working through the clinical logic.
Overall, the results show that high benchmark scores can mask a robustness gap, because small format shifts expose shallow pattern use rather than clinical reasoning.
15
47
282
79,365

🧪 The Benchmarks
Text-only coverage includes MedQA, MMLU medical subsets, and official USMLE self‑assessment PDFs, which together check factual recall and clinical reasoning across many specialties.
Multimodal coverage includes MedXpertQA MM, a harder set with images plus nd VQA-RAD, a radiology set with 2,244 Q‑A pairs, 314 images, and 251 yes/no test cases.
MedXpertQA in total spans 4,460 questions across 17 specialties and 11 body systems, which makes it useful for stress‑testing expert reasoning.

2
0
6
595
⌨️ The Prompting Setup
Each example runs as a 2‑turn chat, first asking for a chain of thought rationale with “Let’s think step by step”, then forcing a final single‑letter choice.
For visual questions, images are attached to the first turn as image_url, the reasoning stays ond turn again narrows to one letter, which makes scoring clean and comparable.

1
0
3
471
👩⚕️ Human Comparison
Against pre‑licensed human experts on MedXpertQA, GPT‑4o trails by 5.03% to 15.90% on several axes, but GPT‑5 flips this, beating experts by +15.22% and +9.40% on text reasoning and understanding, and by +24.23% and +29.40% on multimodal reasoning and hifts the model from human‑comparable to consistently above human on these standardized, time‑boxed evaluations.
Against pre‑licensed human experts on MedXpertQA, GPT‑4o trails by 5.03% to 15.90% on several axes, but GPT‑5 flips this, beating experts by +15.22% and +9.40% on text reasoning and understanding, and by +24.23% and +29.40% on multimodal reasoning and hifts the model from human‑comparable to consistently above human on these standardized, time‑boxed evaluations.

Aug 30, 2025 · 7:40 AM UTC
1
0
3
444
🧪 A Representative Case
The model links repeated vomiting, suprasternal crepitus, and CT findings, flags likely esophageal perforation, and recommends a Gastrografin swallow as the next step.
It explains why alternatives like antiemetics or supportive care alone would miss a owing structured clinical reasoning, not just pattern matching.

1
0
4
452
🧭 What this all means
A single prompting recipe, zero‑shot chain of thought plus a forced final letter, is enough to expose the gap between model generations in both text and image settings.
The biggest jumps appear where the task needs multi‑hop reasoning across images and narrative context, exactly where older systems lagged.
2
0
4
1,381
Paper – arxiv.org/abs/2508.08224
Paper Title: "Capabilities of GPT-5 on Multimodal Medical Reasoning"
Paper Title: "Capabilities of GPT-5 on Multimodal Medical Reasoning"
0
2
7
1,376