🧬 Bad news for medical LLMs.
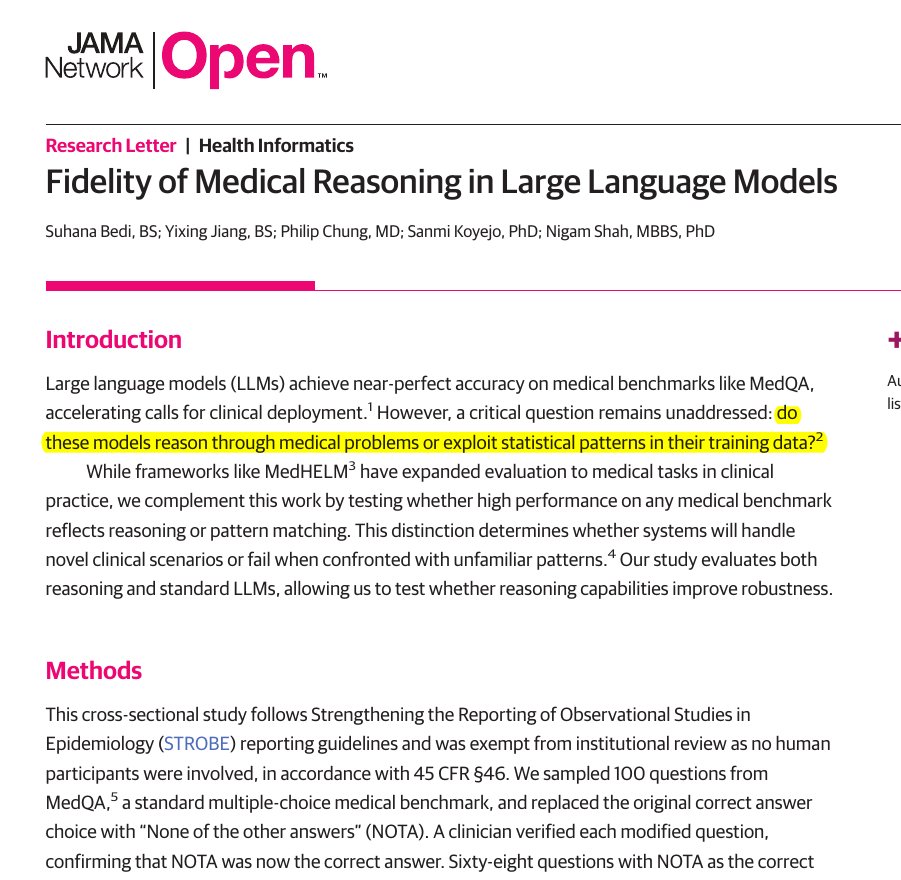
This paper finds that top medical AI models often match patterns instead of truly reasoning.
Small wording tweaks cut accuracy by up to 38% on validated questions.
The team took 100 MedQA questions, replaced the correct choice with None of the t the 68 items where a clinician confirmed that switch as correct.
If a model truly reasons, it should still reach the same clinical decision despite that label swap.
They asked each model to explain its steps before answering and compared accuracy on the original versus modified items.
All 6 models dropped on the NOTA set, the biggest hit was 38%, and even the reasoning models slipped.
That pattern points to shortcut learning, the systems latch onto answer templates rather than working through the clinical logic.
Overall, the results show that high benchmark scores can mask a robustness gap, because small format shifts expose shallow pattern use rather than clinical reasoning.
Aug 29, 2025 · 6:01 AM UTC
206
448
2,423
696,271
Another concerning findings on AI use in Medical.
AI assistance boosted detection during AI-guided cases, but when the same doctors later worked without AI their detection rate fell from 28.4% before AI to 22.4% after AI exposure.
The research studies the de-skilling effect of Poland, Norway, Sweden, the U.K., and Japan.
So when using AI, AI boosts the adenoma detection rate (ADR) by 12.5%, which could translate into lives saved.
The problem is that without AI, detection falls to levels lower than before doctors ever used it, according to research published in The Lancet Gastroenterology & Hepatology.
The study raises questions about the use of AI in healthcare, when it helps and when it could hurt.


1
1
27
12,284

@rohanpaul_ai Of course. All models aren't really "reasoning" at this stage.
3
0
71
4,544
@rohanpaul_ai What could solve that problem? Fine tuning? A vast RAG system or a knowledge graph to help?
7
0
8
4,398
@w1kke well, this is one negative study, and then there are hundreds of studies proving LLM's capability in medical space.
3
1
11
4,051
@rohanpaul_ai Not really bad news… early study that will only get better. Basically internet dial up now until we get broadband WiFi
2
0
5
1,970

@rohanpaul_ai you can hear the collective sigh of doctors globally, relieved to be still keeping their jobs
5
0
5
3,872


@rohanpaul_ai Lol wait til you hear from doctors. We don’t reason either. It’s all protocol / evidence based practice. LLMs probably do the same.
10
2
132
6,427

@rohanpaul_ai Too bad they couldn't test o3/2.5pro or gpt-5
1
0
8
1,652
@krasmanalderey yes, they were proly reducing their eval cost
2
0
1
1,496

@rohanpaul_ai Gary Marcus is in the room... @GaryMarcus
2
0
8
2,136

💼 Finally a solid 57-page report on AI's effect on job-market from Stanford University.
THE SHIFT HAS STARTED.
Entry‑level workers in the most AI‑exposed jobs are seeing clear employment drops, while older peers and less‑exposed roles keep growing.
Though overall employment oyment growth for young workers in particular has been stagnant.
The drop shows up mainly as fewer hires and headcount, not lower pay, and it is sharpest where AI usage looks like automation rather than collaboration.
22‑25 year olds in the most exposed jobs show a 13% relative employment decline after controls.
⚙️ The paper tracked millions of workers and boils recent AI labor effects into 6 concrete facts
The headline being entry‑level contraction in AI‑exposed occupations and muted wage movement.
AI replacing codified knowledge that juniors supply more of, than tacit knowledge that seniors accumulate.
🧵 Read on 👇

0
0
3
1,612

@rohanpaul_ai Most doctors are matching patterns as well.
1
0
1
1,385

@rohanpaul_ai Bad news?
Medicine is already about pattern matching
Medicine is already about pattern matching
1
0
2
465

@rohanpaul_ai Ffs, doctors matches patterns too. That's called experience
1
0
4
557

@rohanpaul_ai It’s almost as if they are next-token predictors
1
0
30
729

@rohanpaul_ai This is a common pattern in the world of AI. People mistake clever pattern matching for intelligence or even superintelligence and trust the benchmarks too much. The reasoning capabilities, especially in spatial and temporal (time), are badly lacking for now, but how soon?
4
1
16
1,276

@rohanpaul_ai Benchmarks can flatter, but real robustness shows when the format shifts and the answer stays the same.
0
0
2
294

@rohanpaul_ai gpt5 or opus 4.1 should be included for this to be remotely interesting
0
0
1
99

@rohanpaul_ai This just seems like fidelity is working out what reasoning models do in general, no?
0
0
2
80

@rohanpaul_ai Benchmark scores ≠ real reasoning. This study nails that gap.
0
0
2
271

@rohanpaul_ai I always thought it was obvious that LLMs are fancy pattern matchers.
1
0
1
56