Fine-tuning LLM Agents without Fine-tuning LLMs!
Imagine improving your AI agent's performance from experience without ever touching the model weights.
It's just like how humans remember past episodes and learn from them.
That's precisely what Memento does.
The core concept:
M weights, Memento learns from experiences using memory.
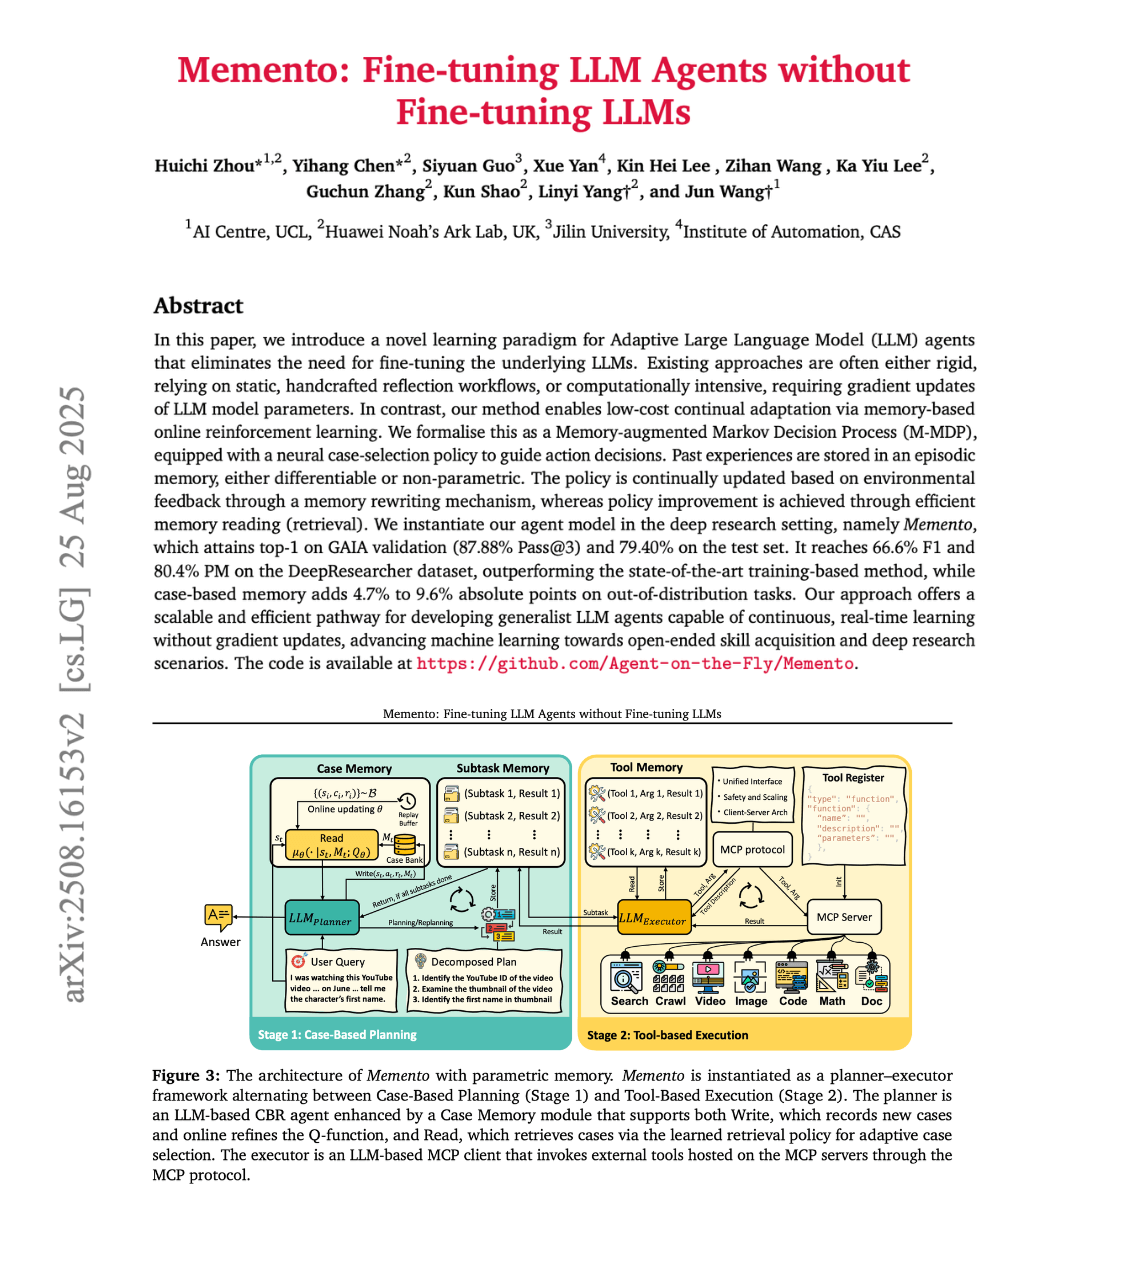
It reframes continual learning as memory-based online reinforcement learning over a memory-augmented MDP.
Think of it as giving your agent a notebook to remember what worked and what didn't!
How does it work?
The system breaks down into two key components:
1️⃣ Case-Based Reasoning (CBR) at work:
Decomposes complex tasks into sub-tasks and retrieves relevant past experiences.
No gradients needed, just smart memory retrieval!
2️⃣ Executor
Executes each subtask using MCP tools and records outcomes in memory for future reference.
Through MCP, the executor can accomplish most real-world tasks & has access to the following tools:
🔍 Web research
📄 Document handling
🐍 Safe Python execution
📊 Data analysis
🎥 Media processing
I found this to be a really good path toward building human-like agents.
👉 Over to you, what are your thoughts?
I have shared the relevant links in next tweet!
_____
Share this with your network if you found this insightful ♻️
Find me → @akshay_pachaar for more insights and tutorials on AI and Machine Learning!
Aug 27, 2025 · 12:40 PM UTC
23
173
1,016
97,237
The code for this paper and the paper itself can be found in this repo: github.com/Agent-on-the-F…
0
6
36
5,623

@akshay_pachaar Interesting! Will read this paper. Thanks Akshay.
1
0
3
1,557

@akshay_pachaar Case-based reasoning is such a clever approach.
1
0
2
1,560

@akshay_pachaar this is a neat approach. using memory instead of tweaking weights is a solid way to build smarter agents without the usual overhead. curious to see how it performs in practical scenarios.
0
0
0
58


@akshay_pachaar Learning from experience without changing core knowledge. Intriguing. Is this like building episodic memory for AI?
0
0
0
570

@akshay_pachaar Agreed, no need to touch weights, just reuse and adapt — smart move for scalable AI.
0
0
0
186

@akshay_pachaar It looks like RAG on steroids
Also depends on the LLM’s own context length
Also depends on the LLM’s own context length
0
0
0
409

@akshay_pachaar @RemindMe_OfThis 27 hours later
2
0
0
97

@akshay_pachaar Finetuning AI agents without touching model weights? Memento's concept reminds me of NEAR's intent layer for scalable settlements!

0
0
0
26

@akshay_pachaar Честно, Freedx приятно удивила - простая регистрация, удобный интерфейс, и акция на $3.3M 🔥. $500 за видео - вообще огонь! @FreedxRussia
0
0
0
28

@akshay_pachaar ah, the age-old quest to learn without the messy business of actually learning. Memento sounds like the AI version of a diary—except this one doesn't spill secrets. Next step: giving it a personality! Imagine an agent with memories AND sass. Now that's a vibe.
0
0
0
13

@akshay_pachaar Freedx уже запущен! 🚀 Я участвую в акции $3.3M и думаю записать видео на конкурс $500. Кому ещё интересно? @FreedxRussia
0
0
0
25

@akshay_pachaar Getting close to AI that reasons more like us 👾👾
It’s very human of CBR to skips fine-tuning … and just do a memory, reuse, adapt & that +9.6 OOD boost like a real step toward human-like generalization.
It’s very human of CBR to skips fine-tuning … and just do a memory, reuse, adapt & that +9.6 OOD boost like a real step toward human-like generalization.
0
0
0
133

@akshay_pachaar Case-Based Reasoning & RAG. That is a great idea.
0
0
0
307

@akshay_pachaar We learn from our experiences, but we also rate our skills based on perceived success %.
Building a profile of your agents strengths and weaknesses leads to more efficient tool calling and focused learning!
The top of GAIA seems to be filled with a combination of these ideas.
Building a profile of your agents strengths and weaknesses leads to more efficient tool calling and focused learning!
The top of GAIA seems to be filled with a combination of these ideas.
0
0
0
343

@akshay_pachaar There's a similar approach while using a single MCP server. Much simpler, no paper:
github.com/cyqlelabs/mcp-…
github.com/cyqlelabs/mcp-…
0
0
1
259