
Jeremy Howard retweeted

We ran @mirendil's new base model on Baseten's private codebases; that is, code it's never seen. Mirendil-Base-Large had the lowest bits per byte (a tokenizer-independent measure of perplexity) of any model we tested.
We're excited to be the inference partner to serve Mirendil Mirendil team on this launch!
We're excited to be the inference partner to serve Mirendil Mirendil team on this launch!

9
18
224
51,256
Jeremy Howard retweeted

People assume that in an AI doing formal verification world, they can take their existing codebase, ask AI to prove it correct, and get either a proof or a bug.
Sadly reality has a few bones to pick with this, and one of them is the "existing codebase" part. And that's due to the good ol' halting problem.
The short of it is that there is no general purpose algorithm that takes any program and input and correctly determines whether it will terminate or run forever. With a few mathematical flourishes we can extend that to "Rice's theorem" and prove this is true for any nontrivial semantic property, meaning we can't automatically prove arbitrary things about arbitrary programs.
Now obviously we can prove some things about some programs, or else formal verification wouldn't exist as a field. The trick is that we write the code in a style suitable for verification. One example of this is totality: in Lean, all functions must be guaranteed to return a value for all inputs. If we want some code that runs forever (like f.ex a server), instead of `while true` we do `while (i < 10^60)` so that it's guaranteed to terminate and return a value (after the end of the universe).
(Totality is also why, in Lean, `1/0 == 0`. If you convert your code to Lean without accounting for this, you could have correct lean but incorrect code!)
Another "style" we use is state machines. Even if your code doesn't quite fit an SM architecture, if you want to prove it at scale, you're probably going to go with a state machine. State machines are the carcinisation of provable code.
Hopefully by now the problem is clearer: even if your codebase is objectively correct, it might not be in the right shape to be proven correct!
Okay, just have the AI rewrite your codebase into another form, right? Two problems. One: you don't know if you've introduced errors in the rewrite because you can't prove them equivalent (since one of them is not in a provable shape). Two: making code more verifiable can make it worse on other metrics, like modifiability, performance, and complexity. And now you've got the old bugbear of software engineers, the dreaded tradeoff.
Now, don't get me wrong, formal verification has a huge role in the future of software, but it's not going to be a breezy "prove my Ruby thx" Claude prompt. It's still going to take work and expertise on our parts to prove our code, and to strike the right balance between formal verification and other forms of correctness.
This is one reason I'm so excited to be working at @AntithesisHQ , which tackles a lot of the same properties as proof methods, but verifies them with "deterministic simulation testing" and fuzzing instead of with a proofs. So it's not as thorough and doesn't give you confidence in all inputs, but it automatically works on pretty much any code shape. I've literally grabbed open source projects off Github, told Claude "check properties XYZ in Antithesis thx", and gotten bug reports back. No state machine rewrites needed.
24
48
247
19,720

I'm happy to share that Mojo and MAX are now fully open - for development, extension, and commercial use! This includes the full Mojo programming language, but also the MAX graph compiler, MLRT runtime internals, and hardware abstraction logic.
Get your agents going!👇
Get your agents going!👇
43
185
1,435
70,419

@clattner_llvm @jeremyphoward mojo/MAX as the backend for BPL wen? :D
1
0
1
369
Jeremy Howard retweeted
I'm happy to share that Mojo and MAX are now fully open - for development, extension, and commercial use! This includes the full Mojo programming language, but also the MAX graph compiler, MLRT runtime internals, and hardware abstraction logic.
Get your agents going!👇
Get your agents going!👇
43
185
1,435
70,419
Jeremy Howard retweeted

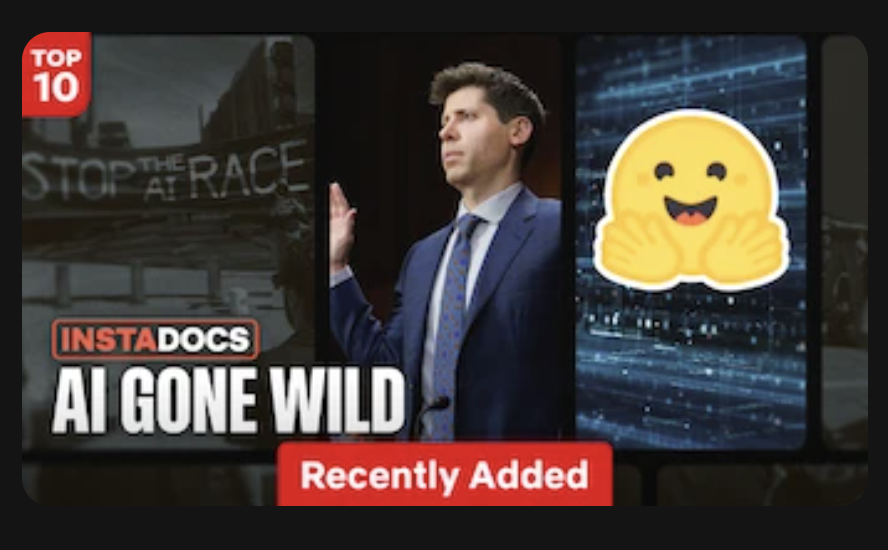
Just watched the @netflix Instadocs about the @OpenAI cyberattack on @huggingface. Super disappointing, as they went for maximum anthropomorphism of the technology and full doomer mode.
I spent more than two hours with them trying to correct all their mistakes and ground this in t agents are technological systems, not aliens. But it looks like the drive to scare people for maximum views was too strong.
Also, they didn’t mention the lack of containment and monitoring of the agents, how closed-model safeguards blocked our defensive work, or how we defended ourselves with AI using an open model. And that we still lack a lot of information and transparency, including full agent traces and that companies need to remain accountable for what their agents do.
It ends up being a fun sci-fi movie though!
247
342
2,311
190,632
Jeremy Howard retweeted

🚀 Introducing DeepInfer, our in-house inference framework, now fully open source!
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/De…
1/4
Powering DeepSeek-V4.1-Flash at scale with high throughput and low latency. We’re sharing our production stack to help the community lower compute costs, reduce energy use, and make AI more affordable.
🔗 github.com/deepseek-ai/De…
1/4
1,615
4,873
42,946
6,636,591
Jeremy Howard retweeted

We now have state-of-the-art pre-trained base models in the 3T-parameter weight class, built entirely in-house at MAI.
Post-training results coming soon -- stay tuned!
Lots of details in our technical blog post.
microsoft.ai/news/frontier-…
Post-training results coming soon -- stay tuned!
Lots of details in our technical blog post.
microsoft.ai/news/frontier-…
148
356
3,477
1,359,705
Jeremy Howard retweeted

I’m very pro AI, but in terms of the Twitter software engineering discourse I see mostly people doing single person vibe coding, or AI labs with infinite compute Ralph Wigguming giant codebases.
What I don’t see are people doing AI software engineering that has multiple humans contributing to a single code base, each using AI agents, working in a non-commodified domain.
In this world I believe the AI hype bois are over their skis in terms of proclaiming the death of software engineering. Maybe in the future but for now in this 6 month gradient of the Singularity the reality on the ground are things like:
- Using CI as a harness to ensure agentic coding is correct and validated
- Balancing velocity with other concerns (reliability, choosing the right problems, quality, etc)
- Making sure the system has an architecture and philosophy so that you don’t end up with spaghetti
- Still doing code reviews (though they can be augmented with AI) to ensure you don’t end up with cognitive debt.
- Balancing AI costs, and mixing in “human tokens” where appropriate
- etc
I’d love to hear more from others in this domain! Ie those not just doing solo development projects or AI labs with infinite compute
117
20
516
50,131
Jeremy Howard retweeted

Introducing Indra, a 1M parameter OCR model:
- 49 pages/s on CPU, 11x faster than PaddleOCR and 17x Tesseract
- Beats them on OmniParseBench text (41.3 vs 35.8 and 19.3)
- Full layout and line bounding boxes
- 49 pages/s on CPU, 11x faster than PaddleOCR and 17x Tesseract
- Beats them on OmniParseBench text (41.3 vs 35.8 and 19.3)
- Full layout and line bounding boxes
128
255
2,905
148,647
Jeremy Howard retweeted

(1/7) I'd like to provide some additional context for the remarks that can be found in this interview.
(2/7) My discomfort with the attention being paid to existential risk---and with the ongoing dominance of the public discussion of such risks by a few so-called thought leaders---is that there's an elephant in the room that is being missed. That elephant is the effect of all of this discussion on young people, and indeed the effect---beginning with social media a decade ago---of information technology on young lives broadly speaking.
(3/7) I recently read an interview by Jill Lepore in which she reports on discussions that she had recently with a group of college students: "They had just three things to say. One, social media completely destroyed their childhoods. Two, AI is destroying their college education and their likely prospects for employment. And three, what the hell are we all doing?" To add a fourth bullet that I've heard in similar discussions: "I'm not going to have children, because the existential risk is just too high."
(4/7) Please contemplate such a statement, those of you who think that it's OK that the public, widely diffused, discussion coming from seemingly authoritative figures is so adamant about existential risk.
(5/7) Let me add that I have little interest in a debate about what "superintelligence" might mean, or whether we're currently seeing the emergence of superintelligence. For what it's worth, I would certainly agree that the solution of extremely challenging math problems (for example) exhibits a very impressive form of intelligence, although I would want to argue that such intelligence is impossible to dissociate from the collective of humans that provided data to the machine learning system (which itself has become a kind of collective).
(6/7) Such philosophical debates are entertaining and even important, but when they then head in the direction of "when such superintelligence emerges, there's a good chance that it will want to kill all humans", I say "science fiction". Again, I don't think that it's bad to consider such thoughts, but I strongly believe that it's bad for society, and especially young people, for such thoughts, unaccompanied by any serious real-world analysis, to become a dominant form of discourse of the era.
(7/7) We are damaging human lives, and the consequences of that damage will no doubt be a major theme of the next several decades.
49
235
1,201
151,722
Jeremy Howard retweeted
We made a fair OCR benchmark. And we're not ranked first.
Introducing OmniParseBench - 16k tests across 90 languages with consistent, interpretable scoring.
Introducing OmniParseBench - 16k tests across 90 languages with consistent, interpretable scoring.
16
50
370
19,980
Narrator: he was not, in fact, allowed to say “I’m quite unhappy with much of what OpenAI does.”
I’m quite unhappy with much of what OpenAI does.
I am very happy that I’m allowed to say “I’m quite unhappy with much of what OpenAI does.”Community noteKorbak was fired ~3 weeks later. He says for safety concerns/METR talks (his job); OpenAI says mishandling sensitive info, not for speaking out.
x.com/tomekkorbak/st…
x.com/OpenAINewsroom…

24
67
1,998
90,920
Jasmine says that she accidentally accessed an executive's email that OpenAI had explicitly given her access to, even although she had explicitly requested that OpenAI remove her access, and IT had failed to do so.
Which implies Jasmine was fired for IT's failure?
Which implies Jasmine was fired for IT's failure?
OpenAI fired me last week, along with two of my safety colleagues. I was given one reason: that I accessed an executive's email. I want to say this plainly, because too many of OpenAI’s history is smoke and mirrors when people disappear:

23
12
544
85,373
Looks like you copied Chandra OCR 2 into your repo, renamed it, changed the license, and made the output worse (your olmocr score is 83.8 vs our 85.8).

Introducing interfaze-1-lite, the first general open-weight model for deterministic work
OCR, speech-to-text, extraction, classification and more
It returns confidence scores and metadata like bounding boxes on every run
huggingface.co/interfaze-ai/i…Community noteInterfaze appears to have copied the Chandra OCR 2 model, renamed it, and changed the license, without disclosing that the model is not orginal. See x.com/VikParuchuri/s…

74
119
2,640
156,298

I think you're confused, we used a wide range of models and we did credit them in the repo. We thought Chandra was great and literally linked you guys there. Along with Qwen and a bunch of other models that was used to develop it. we weren't trying to hide that fact hence why everything is open and linked.

13
0
25
15,475
@yoeven @VikParuchuri A matching SHA256 is a really respectful way to show how inspired you are.
1
0
40
874
Jeremy Howard retweeted
Looks like you copied Chandra OCR 2 into your repo, renamed it, changed the license, and made the output worse (your olmocr score is 83.8 vs our 85.8).
Introducing interfaze-1-lite, the first general open-weight model for deterministic work
OCR, speech-to-text, extraction, classification and more
It returns confidence scores and metadata like bounding boxes on every run
huggingface.co/interfaze-ai/i…Community noteInterfaze appears to have copied the Chandra OCR 2 model, renamed it, and changed the license, without disclosing that the model is not orginal. See x.com/VikParuchuri/s…
74
119
2,640
156,298

Does some university want to host me (George) and offer a winter semester Compilers for Machine Learning course?
12+ weeks, hands on, build a compiler. Syllabus in next tweet. Needs a student body capable of doing this work and leadership capable of recognizing how SOTA this is.
12+ weeks, hands on, build a compiler. Syllabus in next tweet. Needs a student body capable of doing this work and leadership capable of recognizing how SOTA this is.
169
98
2,856
183,642
@madhavajay @__tinygrad__ Would be a fascinating course though. Hope it happens, and it gets recorded :)
0
0
10
3,778
Jeremy Howard retweeted

Today we're unveiling Trillium Labs @trillium_labs, a new non-profit to foster the open science of frontier AI. We're building open post-training recipes and will expand into open infra to study RSI, reward-hacking, multi-agent systems, and whatever comes next.
We're built ange that you need more eyes to solve hard technical problems. We have faith in the scientific methods and communities that humanity has built, and worry that AI is becoming too closed to utilize them.
Trilliums are wildflowers that bloom briefly in the spring, before the forest canopies fill out. Though they are small, they lay the foundation for the cycles of growth and nourishment through the rest of the year. At Trillium Labs, the recipes will be the slow nutrients for the seasons and the model releases will be the blooms. Building an institution dedicated to this is needed because, much as nature’s trilliums are slow to expand and grow, the open-ecosystem needs time and dedicated resources to catch up.
I co-founded with with a long-time friend and collaborator Tom Zick (@thesezickbeats). We're hiring (full time + student collabs/interns), we're fundraising, and we're looking for compute. Please get in touch if you're interested in helping out. Offices based in the Bay Area and Cambridge MA, remote okay.
I’m in the Bay Area until for The Curve and COLM to connect with people who are interested. We’re thankful to have initial support from Halcyon Futures and Schmidt Sciences with more funding en route to enable our ambitions of scaling. Our advisors @Thom_Wolf, @HannaHajishirzi, @gneubig and @ctnzr have been instrumental to building the ecosystem that exists today, and I’m stoked to get to keep working with them.

252
302
3,283
260,027
Jeremy Howard retweeted

The Pareto frontier is misleading ❌ for general users. Price it by subscription instead of API. With cache hits, Opus 5.5 with Claude Code 20x has already killed every other model.
59
79
1,119
95,001
@badlogicgames Me too! (Although my friendship was with Astra.)
1
0
10
2,816