Gemini 2.5 Flash Image (Nano Banana) best practices 🍌🍌🍌
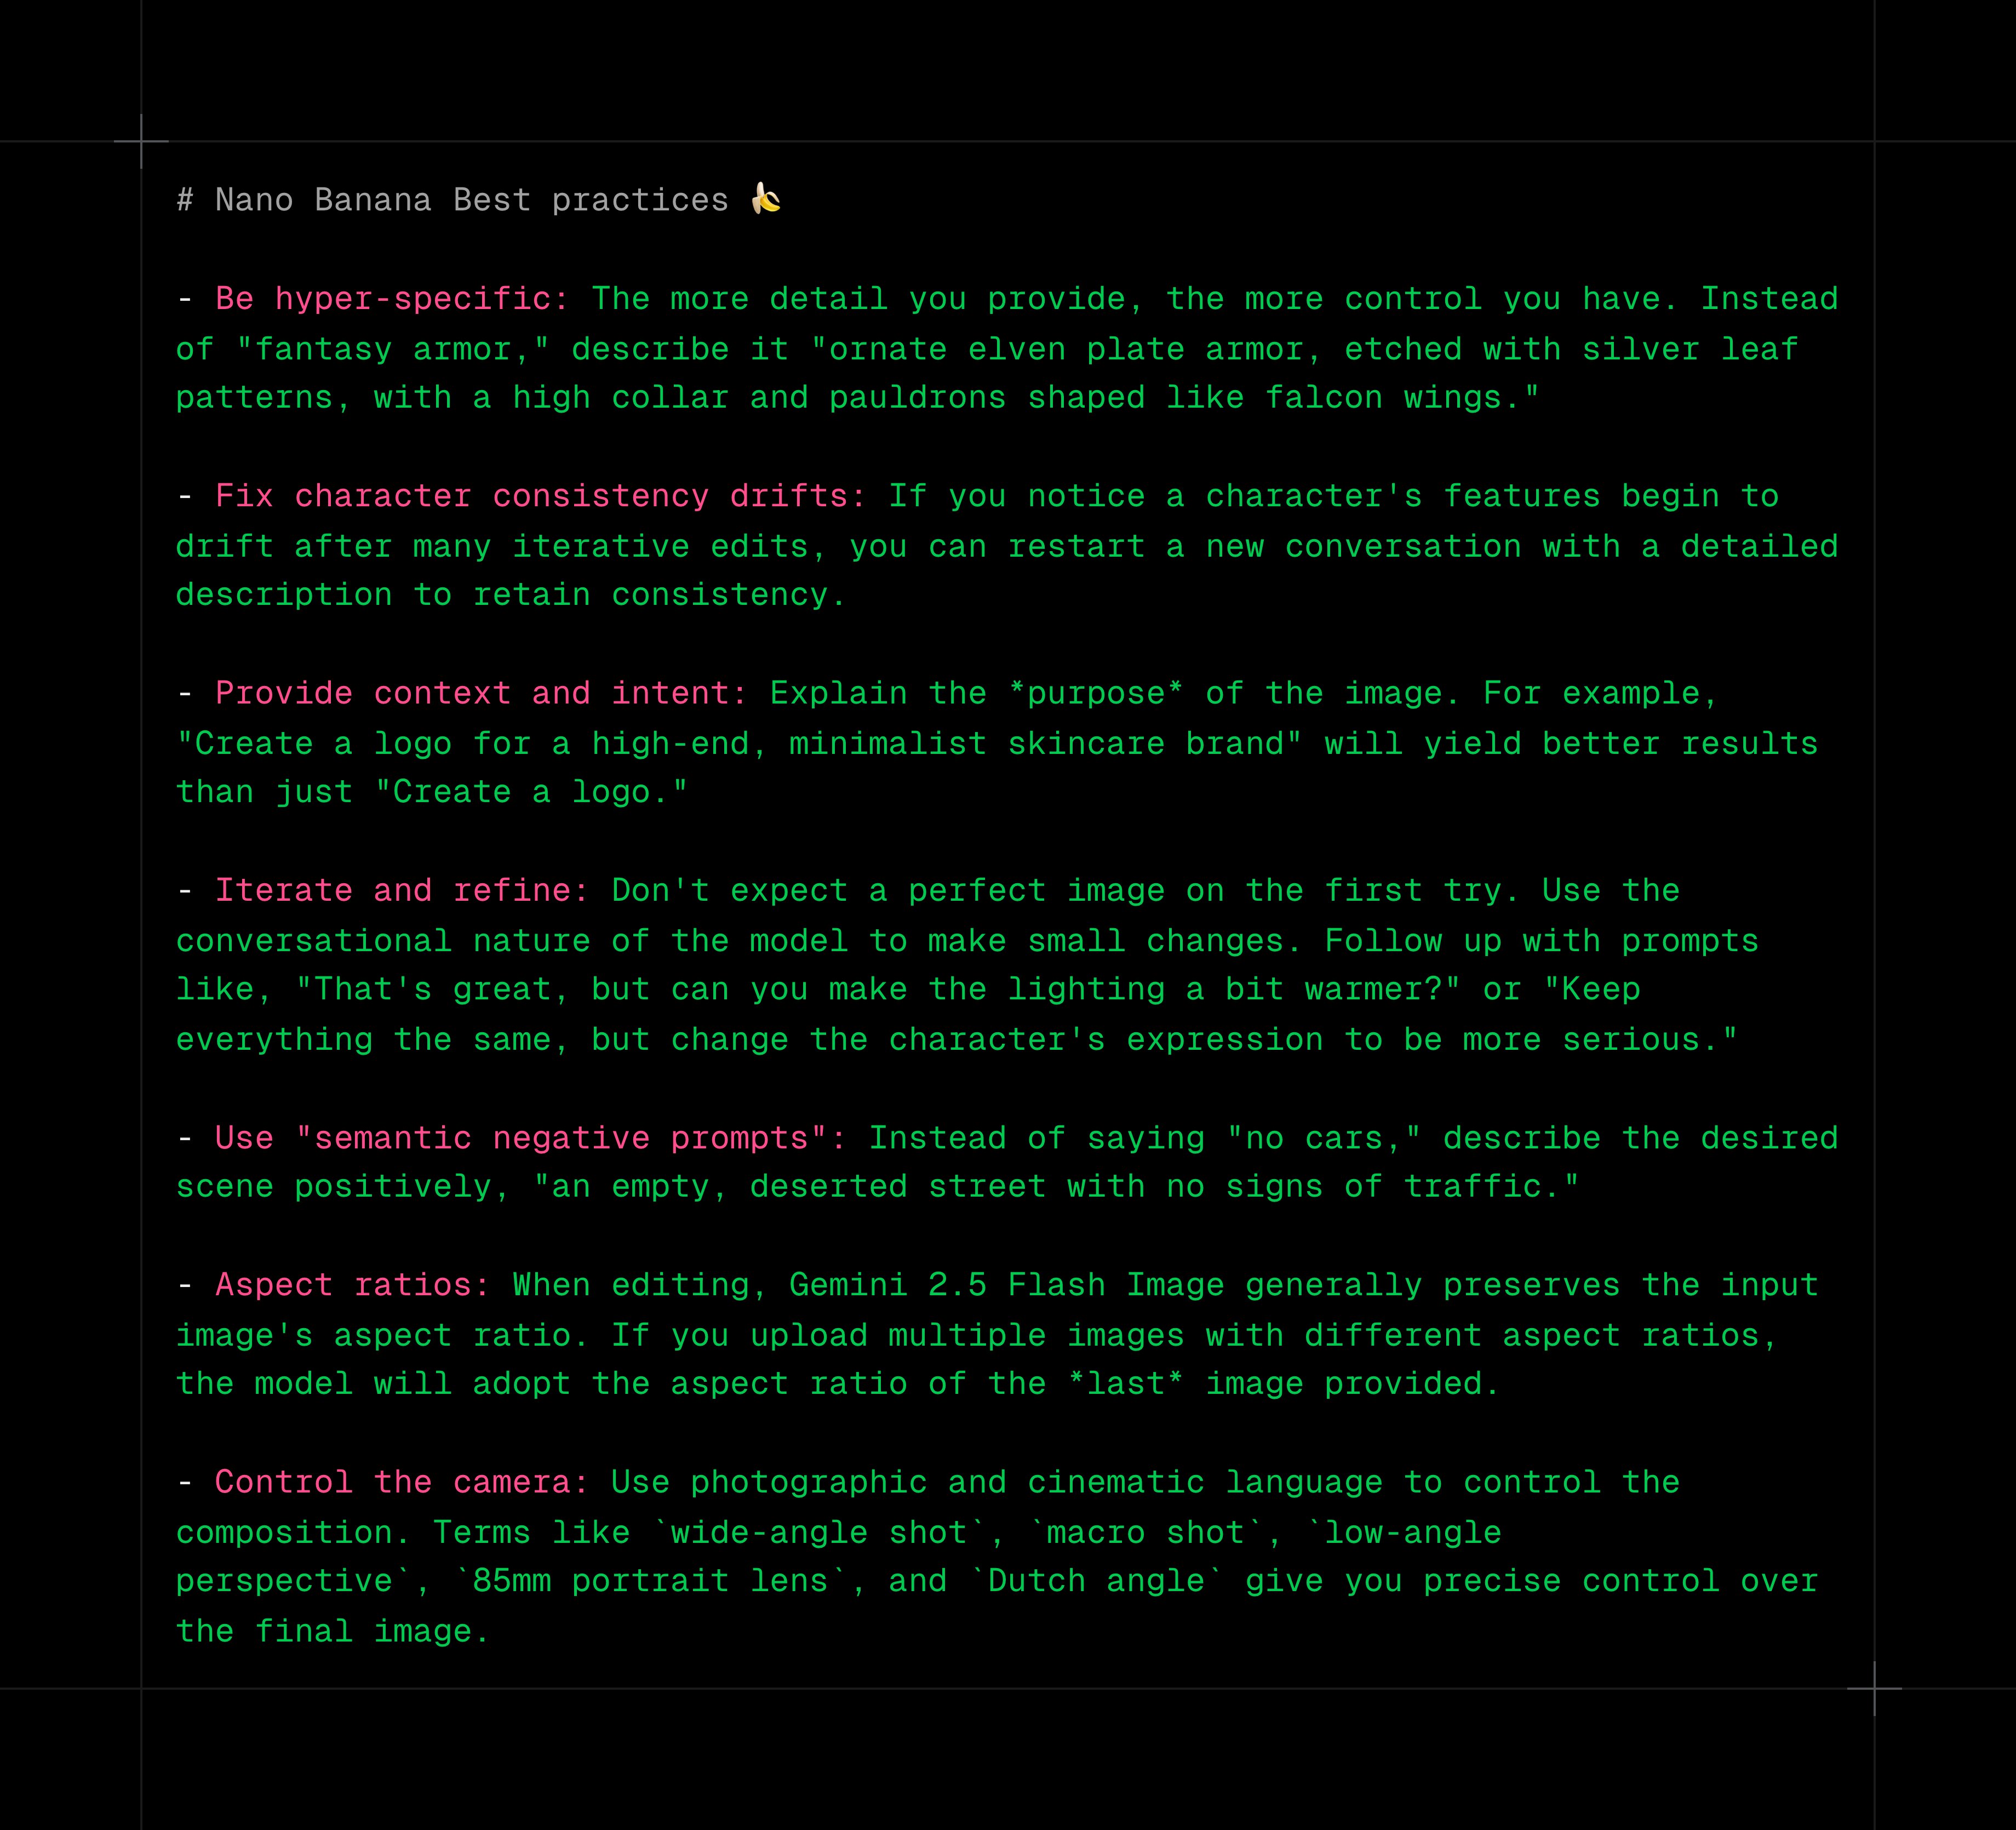
- Be hyper-specific: The more detail you provide, the more control you have. Instead of "fantasy armor," describe it "ornate elven plate armor, etched with silver leaf patterns, with a high collar and pauldrons shaped Fix character consistency drifts: If you notice a character's features begin to drift after many iterative edits, you can restart a new conversation with a detailed description to retain consistency.
- Provide context and intent: Explain the *purpose* of the image. For example, "Create a logo for a high-end, minimalist skincare brand" will yield better results than just "Create a logo."
- Iterate and refine: Don't expect a perfect image on the first try. Use the conversational nature of the model to make small changes. Follow up with prompts like, "That's great, but can you make the lighting a bit warmer?" or "Keep everything the same, but change the character's expression to be more serious."
- Use "semantic negative prompts": Instead of saying "no cars," describe the desired scene positively, "an empty, deserted street with no signs of traffic."
- Aspect ratios: When editing, Gemini 2.5 Flash Image generally preserves the input image's aspect ratio. If you upload multiple images with different aspect ratios, the model will adopt the aspect ratio of the *last* image provided.
- Control the camera: Use photographic and cinematic language to control the composition. Terms like `wide-angle shot`, `macro shot`, `low-angle perspective`, `85mm portrait lens`, and `Dutch angle` give you precise control over the final image.
Aug 30, 2025 · 3:12 PM UTC
60
223
1,942
192,035

@_philschmidatio thing was driving me crazy ty!
is there any other guidance for enforcing aspect ratio? just asking in the prompt doesn’t seem to do it but i was thinking a hack could just be to pass a blank image in the ratio i want as the last image and describe my edits with the other inputs
is there any other guidance for enforcing aspect ratio? just asking in the prompt doesn’t seem to do it but i was thinking a hack could just be to pass a blank image in the ratio i want as the last image and describe my edits with the other inputs
2
0
9
2,959

@_philschmid Providing the context and intent has been really helpful in getting perfect images.
0
0
4
2,598


@_philschmid If you’re looking for a diverse range of shot types, this may help. x.com/chidzowtf/stat…
0
0
3
352

@_philschmid Control emerges from specificity. But too much detail can stifle imagination. Find the balance.
0
0
0
459


@_philschmid Are we able to reference input images by index number? e.g. can we say "take the x of the 1st image and the y of the 2nd image"
0
0
0
48


@_philschmid why are we giving Ai engineers a pass on the pisspoor natural language inferences and requiring users to learn these best practices.. Ai is meant to be a tool for humans to understand human language and expectations. We mold it to our whims not change our ways for Ai.
4
0
5
1,880

@_philschmid 9wEkKb76AUZLfWTDGuKxVAw54tX6RneTkKsA7XNwpump
0
0
3
293


@_philschmid It would be really valuable to know if it's possible or not to end up in a "Shadow Ban"-Mode.
Feels from my usage and reading of reports like it.
x.com/MarioHachemer/…
Feels from my usage and reading of reports like it.
x.com/MarioHachemer/…
0
0
2
2,298
@_philschmid At the end of the day , it all boils down to domain knowledge.
The better you have it, the better you know what to prompt and which key words to use.
I think this will not make a lot of jobs disappear , cause most of them require domain knowledge 😅
The better you have it, the better you know what to prompt and which key words to use.
I think this will not make a lot of jobs disappear , cause most of them require domain knowledge 😅
0
0
1
48

@_philschmid Are these applicable to Veo 3 as well?
0
0
1
626

@_philschmid Literally "The Basics of Prompt Engineering"
Applicable not only to the Nano Banana thing
Applicable not only to the Nano Banana thing
0
0
1
251

@_philschmid 9wEkKb76AUZLfWTDGuKxVAw54tX6RneTkKsA7XNwpump
This
This
0
0
0
29
@_philschmid BANANAROOM ca: 9wEkKb76AUZLfWTDGuKxVAw54tX6RneTkKsA7XNwpump
0
0
1
193

@_philschmid 9wEkKb76AUZLfWTDGuKxVAw54tX6RneTkKsA7XNwpump
0
0
1
168


@_philschmid It's the lack of specificity that kills us. We expect the AI to understand everything that we are thinking.
0
0
1
571

@_philschmid Any way to specify the output format ? Dimension and file type ?
0
0
1
772

@_philschmid I'm excited to share that I've created a Gem for the Gemini app! It features a detailed system prompt that guides me step by step through all the necessary information to ultimately craft the perfect prompt. Worked like a charm. It's a pity that I can't share my gem.
0
0
0
44

@_philschmid Period correct camera x.com/renntv/status/…
Tough times ahead for Image Editors like Photoshop if you can be creative and productive just with prompting. New Gemini 2.5 Flash is impressive!

0
0
0
22

@_philschmid within minutes of nano banana going viral google frantically stumbled out the front door pushing the everyone aside, wild eyed, and stuttering, “guys!? the akchual name?! ..is Gemini Flash 2.5 Image!”
0
0
0
220


@_philschmid Thanks. Much inspiration for a lot of fun
0
0
0
125

@_philschmid hyper-specificity, huh? sounds like a recipe for a digital nightmare. next, they'll want us to describe our existential crises in detail too. 🍌
0
0
0
2

@_philschmid Something I learned two years ago before any of this was a trend
0
0
0
271

@_philschmidlid fundamentals that apply broadly across AI image generation models. The emphasis on specificity and iterative refinement is particularly valuable - many users underestimate how much precision in language translates to better visual outputs.
The point about semantic negative prompts is especially insightful. Framing constraints positively rather than as exclusions tends to produce more coherent results across most diffusion models, not just Gemini.
One addition I'd suggest: establishing a consistent 'visual vocabulary' early in a session can help maintain coherence across multiple generations. When you find terminology that produces the aesthetic you want, documenting and reusing those specific phrases creates more predictable results.
The camera control techniques you mention are spot-on for anyone coming from a photography background - these models have clearly been trained on vast amounts of professionally shot and described imagery.
0
0
0
99


