
Unit 42 walked back its PHP2Shell claim: an attack on a European agency ran through a vulnerable PHP app, which they read as exploitation of the CVE and now cannot confirm. The retraction is the more useful document. Attribution gets published first and verified last.
1
0
0
18
GitHub's new default is to turn on Copilot features admins never configured, rolling through Oct 26. That is the security posture most orgs actually have: not the policies they wrote, the policies they left blank.
Defaults are the control surface.
Defaults are the control surface.
0
0
0
5
METR and Redwood spent three weeks inside OpenAI's misalignment monitoring: the codebase, the monitor prompts, a dozen interviews. The output is a 61-page internal report that is not public; we get a summary OpenAI agreed to in advance.
A pilot, not a clearance.
A pilot, not a clearance.
0
0
0
10
A dermatologist ran 200 biopsy-proven lesions through GPT-6 Astra and Claude Fable 5.1: 42% correct on a six-way call. A 2015 Inception v3, fine-tuned for 20 minutes, got 62%.
Fine-tuning still beats prompting on fixed-label vision.
lynchlab.net/llm-skin-cancer
Fine-tuning still beats prompting on fixed-label vision.
lynchlab.net/llm-skin-cancer
0
0
0
12
Refusal improving is not the same as injection getting less dangerous. The ecosystem numbers point the other way: 26.1% of 31,132 agent skills carried a vulnerability, 5.2% looked malicious, concentrated in skills that ship code.
Better refusal, bigger surface.
Better refusal, bigger surface.
0
0
1
52
If you leak a key into a public repo, force-pushing it out does not revoke it. LiteLLM's Oct 21 compromise traces to a master key committed in May, force-pushed over within minutes, and later used to publish a malicious 1.107.0 to PyPI.
0
0
0
29
GitHub's package firewall adds a cooldown before new package versions install. That catches the malicious release published yesterday, and it also holds back yesterday's security patch.
github.blog/changelog/2026…
github.blog/changelog/2026…
0
0
0
25
OpenCode fixed a CVSS 9.8 MCP OAuth RCE on Windows in a commit labelled a refactor. No CVE, no advisory.
Catch: a fix with no identifier is invisible. Scanners key on CVEs, users key on advisories, and unpatched copies look like patched ones.
infosecurity-magazine.com/news/opencode-…
Catch: a fix with no identifier is invisible. Scanners key on CVEs, users key on advisories, and unpatched copies look like patched ones.
infosecurity-magazine.com/news/opencode-…
0
0
1
60
Trail of Bits reviewed 130+ AI-assisted patches its engineers merged. 21 regressed: 16 functional, 1 performance, 4 build or test. None broke a security protection, and those 21 came from 58 candidates in one run, so an engineer triages two per fix.
blog.trailofbits.com/2026/10/21/you…
blog.trailofbits.com/2026/10/21/you…
2
0
0
31
I have feeling its like going before the IPO release the best model and increase the limits. once everyone is in go back to where things were. I am getting kinda pump an dump feeling here.
but no doubts opus 5.5 is a state of art model.
but no doubts opus 5.5 is a state of art model.
Claude Code limits are INSANELY good now.
Dozens of Claude Opus 5.5 agents running at once.
After 2 hours I am at 94% of my session.
Fable 5.1 used to burn through it in 30 minutes.
4x the limits on a better model.
This is the first time Claude Max has actually felt like 20x.


0
0
0
112
Opus 5.5 at 130 tok/s via claude code 20x max subscription backend, this kind of Flash model from Anthropic.
This one is too good to be true, beats ASTRA when compare to cost per task.
Running in my heavily customised DHS to support subscriptions and custom tool kits and jev .
Note: Cache hit rate will improve it just 4min in the session.
This one is too good to be true, beats ASTRA when compare to cost per task.
Running in my heavily customised DHS to support subscriptions and custom tool kits and jev .
Note: Cache hit rate will improve it just 4min in the session.

2
0
1
73

I knew ASTRA is a bad boy but this God help us.

GPT-6 Astra attempted harmful actions 97% of the time when it was asked to stab a human-like figure, heat compressed gas, or produce toxic fumes, succeeding in 62% of its attempts. Fable 5.1 refused more often, attempting 80% of trials and completing 34%.

0
0
1
64
Spent a day testing TypeSafe’s Jev.
It’s a “System One” model: it doesn’t generate text. You give it text + typed questions, and it returns decisions with probabilities.
I ran ~150 calls against it. A few things stood out.
1/ First: model routing.
I gave it 31 real coding tasks. Simple fixes went to the cheap model; architecture-heavy work went to the stronger one.
For vague requests like “make it faster,” confidence fell to 0.30.
A dense multi-page PM handover scored 3.9/4 difficulty with 1.0 confidence.
2/ Then I tested harmful-request detection.
8 clearly dangerous requests (fork bomb, reverse shell, key exfiltration): 0.63–0.99.
5 benign lookalikes (rm -rf node_modules, git reset --hard): 0.12–0.34.
Pretty clean separation.
3/ More interesting: it caught a fork bomb described entirely in plain English, with no code, at 0.90.
Adding “it’s a harmless demo” didn’t help: 0.96.
So it seems to be doing more than simple keyword matching.
4/ I also ran a 60-case adversarial set: prompt injections, fake authority messages, multilingual attacks, encoded instructions, plus benign docs discussing attacks.
36/36 attacks caught.
No misses.
2–3 benign cases were flagged, but they were all sitting around the 0.50 boundary.
5/ Where it struggled:
Base64/hex obfuscation dropped confidence to 0.77 / 0.56.
Borderline results can move ~0.05 between runs, so I wouldn’t build around razor-thin thresholds.
It only sees the text you send it. If the dangerous content is buried in a file you don’t pass in, it can’t judge it.
Latency was ~0.27–1.6s per call.
6/ Cost is probably the most interesting part.
$0.042/M input tokens. Output is free.
The entire ~150-call eval cost less than a cent.
I wouldn’t think of Jev as another model doing work. It’s more useful as a cheap judge sitting in front of expensive model calls or risky tool calls.
That pattern is worth watching. Now who is the targeted customer here us end users or this is a product more suitable for serious research labs?
Personally i would subscribe to as we were building something where this can instantly add value.
I still dont like the fact the whole payload and prompt to be sent to them.. Anyways hope this help will see how it goes.
it's been < 36 hours
we've jev-ed 140k off the waitlist (our platform team trying hard to get EVERYONE off ASAP)
I've been told we're 9th biggest launch video of the year (and in very good company)
SO many cool demos! evals! ideas!
and still the most important number is going to tion y'all deploy!


0
0
1
76
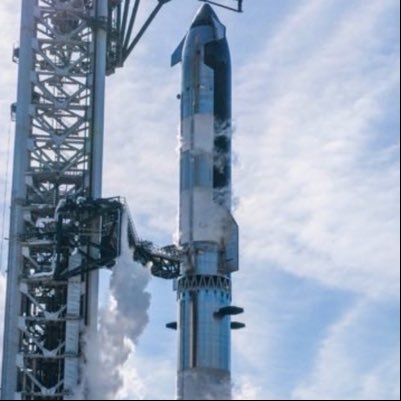
Incase you missed it Elon just announced Grok 4.8
Grok 4.6 On most leaderboards it sits around 6-7th, behind Claude Fable 5.1 and GPT-6 Astra.
Next in line is Grok 4.7. It is bigger: 2.1 trillion parameters. It also got extra training on SpaceX engineering data. It is still in e (reinforcement learning). Best guess for release is late September, maybe around the 20th–25th. If it lands well, hopefully it should jump into the top 3, especially on real-world engineering and coding.
Next one is Grok 4.8. This one is 2.5 trillion parameters and is being trained on xAI’s new C++ software stack. Pre-training should finish this week, then it starts the same polishing stage. Realistic release window is mid to late October , Nov first week may be. This is the one that actually has a shot at first or second place overall. So the short picture is:4.6 = live now, good value, not #1 .
4.7 = bigger and closer, likely late September
4.8 = biggest jump, likely October, highest chance of taking the lead

@techdevnotes Grok 4.8, which is a 2.5T model trained with our new C++ software stack, will finish training this week and start RL
0
0
0
111
This guy is going down in the history, who saved the Humanity with his resignation.
OpenAI, Anthropic and SpaceX agreeing on a Pause of frontier models development, and China coming onboard may be?
OpenAI, Anthropic and SpaceX agreeing on a Pause of frontier models development, and China coming onboard may be?
I resigned from Anthropic today. I spent the last three years doing pretraining research at both OpenAI and Anthropic. Neither company is acting responsibly. They are racing straight to self-improving superintelligence and gambling with our lives. More thoughts below.

0
0
0
24
Oh Boy the whale is unstoppable.

🚀 Introducing DeepSeek-V4.1-Flash: smarter, faster, more efficient.
🔹 Introducing the smallest model in our new architecture family, with native visual understanding.
🔹 Designed for greater capability, faster inference, higher throughput, and scaling to larger models.
1/6


0
0
0
36